
Bringing Inference Programs To Solana
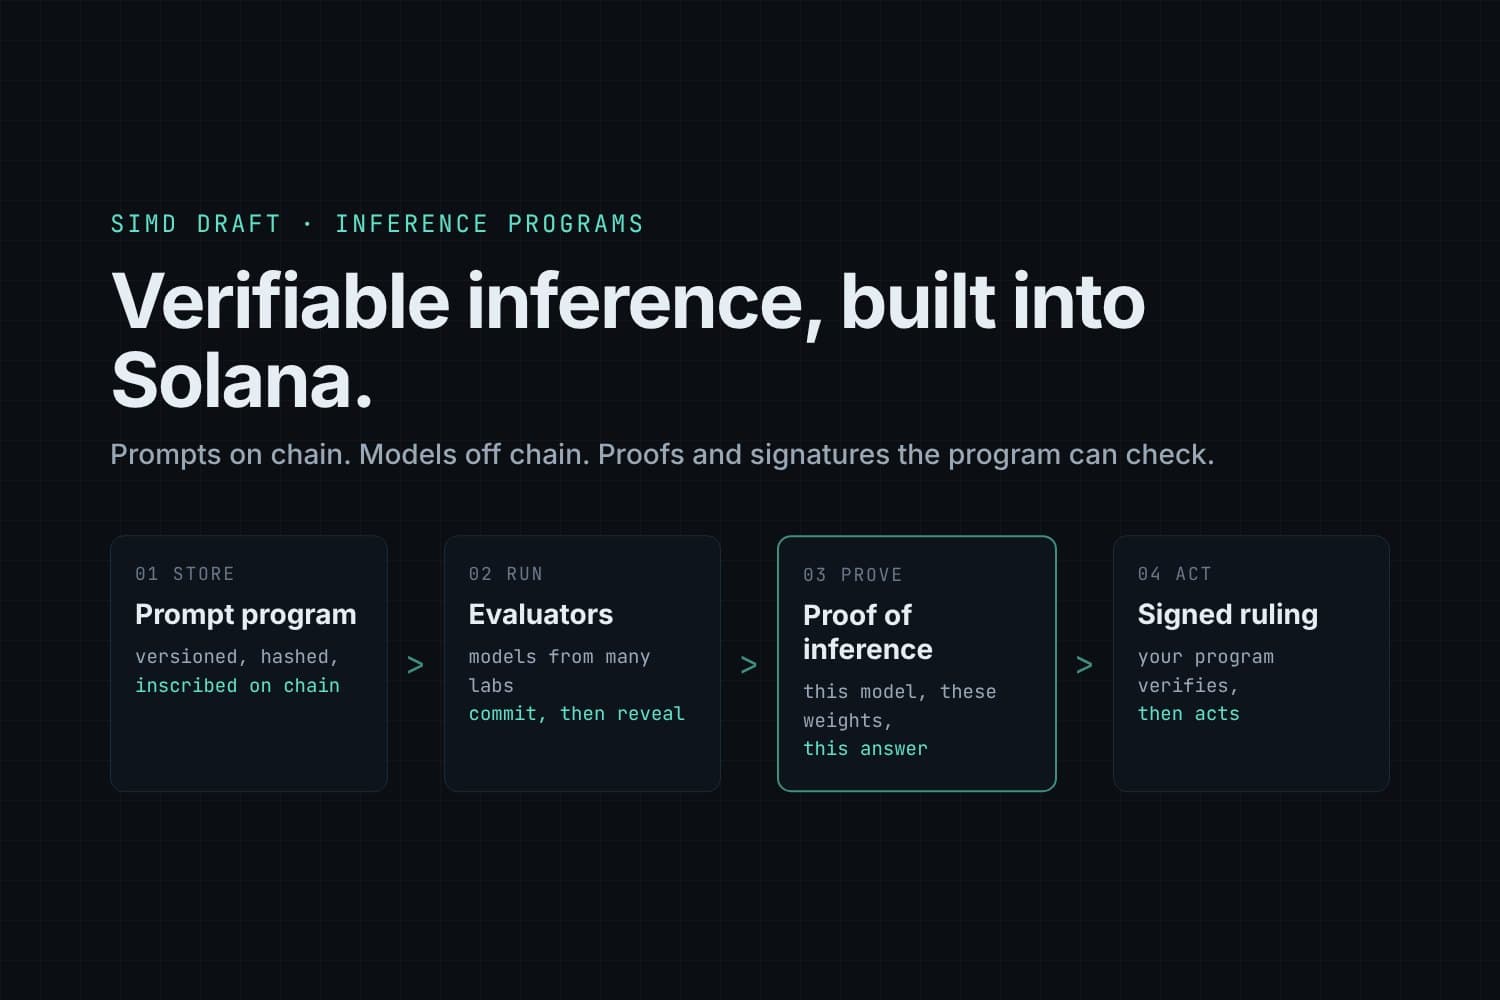
Three draft SIMDs to bring Actually Smart Contracts to Solana: prompts stored on chain, run by models off chain, proven, signed and open to challenge.
Three draft SIMDs. All three are drafts, written to open a discussion, not yet submitted.
- Inference Programs: natural-language programs on chain, their internal context, and how other programs call them, inject external context, shape the jury and pay. (Markdown)
- Inference Evaluators and Attestations: who runs the models, what they commit to, the signed vote each one casts, and proofs of inference. (Markdown)
- Inference Rulings, Disputes and Challenges: the signed ruling programs act on, and how rulings are disputed, challenged with new evidence and overturned. (Markdown)
This started as one draft. It grew large enough that it reads better as three proposals that depend on each other, so each can be reviewed on its own.
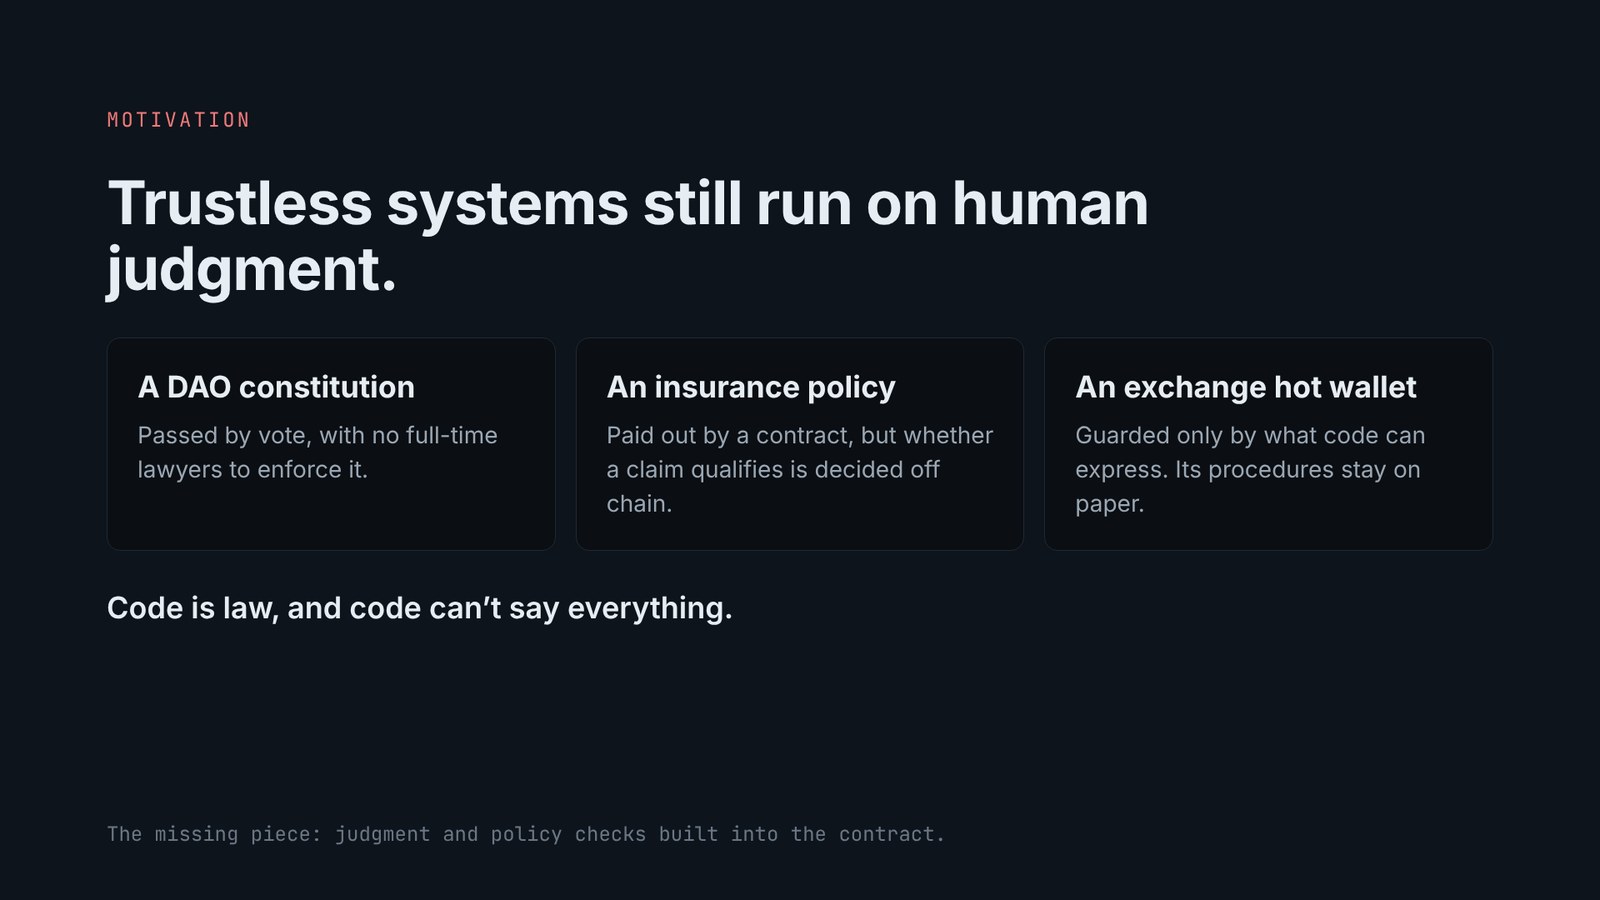
Blockchains have made real progress toward trustless, decentralized systems that run without anyone in charge. But they still lean on people for judgment: discussion, opinion, motives and alignment, all happening off chain. That reliance has been a steady source of inefficiency, and of risk.
A DAO can pass a constitution, but it has no full-time lawyers to enforce it. An insurer can write a policy that a smart contract is meant to pay out on, but deciding whether a claim qualifies still happens off chain, by people. An exchange may want to wrap its hot wallets in procedures that protect user funds, and find it can only enforce what code can express. Code is law, and code can’t say everything.
That’s why we think it’s time to talk seriously about how AI and blockchains can converge to add the missing piece: judgment, and policy checks built into the contract itself. A program should be able to get a second opinion, ask an expert panel, or go to a judiciary for a ruling before it moves funds. Done right, that means better security and more control over how funds are managed.
To that end, we’re introducing Actually Smart Contracts as a SIMD for Solana itself. Yesterday we introduced the idea: smart contracts you can write in English, enforced by a jury of AI models. Today we’re publishing three draft Solana Improvement Documents that would make it a shared standard, so every program, wallet and explorer can use it the same way.
The idea in one paragraph
Store a prompt on chain the way you’d store a program, along with the context that should shape the decision: policies, rules, a constitution, even a link to a DAO discussion. Let any Solana program call it. AI models run it off chain, and each one signs the result on chain: we ran this program, at this version, on this input, and this is the answer. A proof of inference shows which model actually did the thinking. The calling program checks the signatures before it acts.
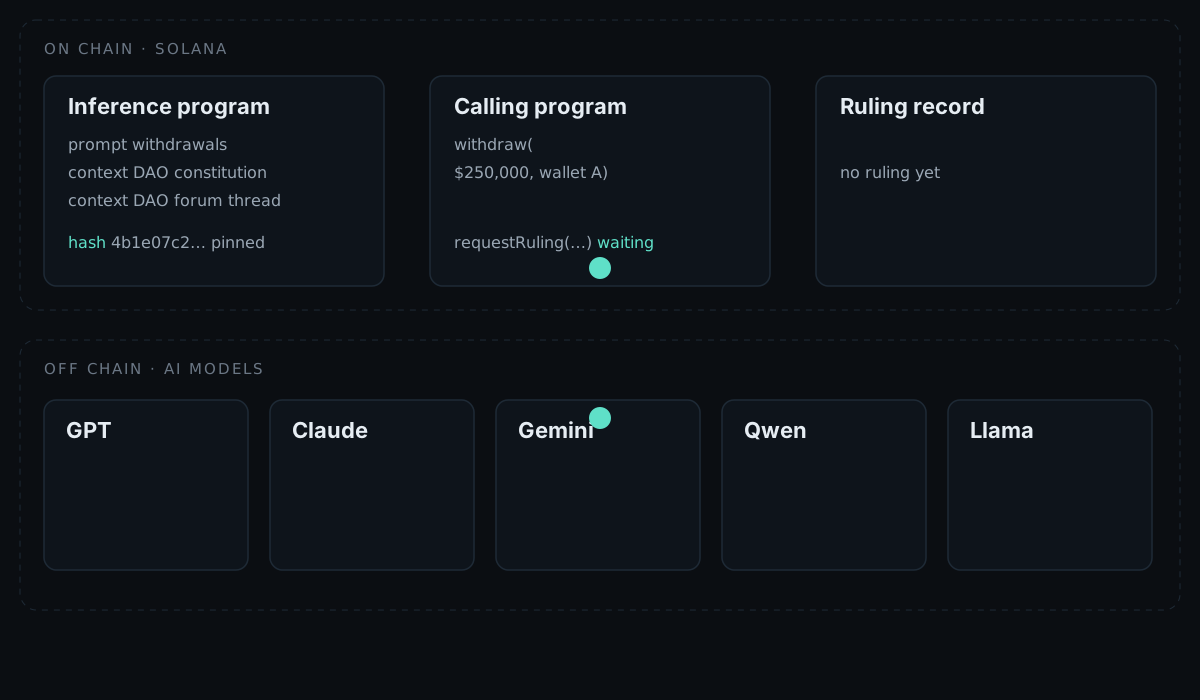
That changes what a smart contract can be. Today a program can only enforce what code can express: balances, signatures, dates. With an inference program, it can enforce a sentence like “the treasury shall not fund political campaigns.”
Why proof of inference is the key
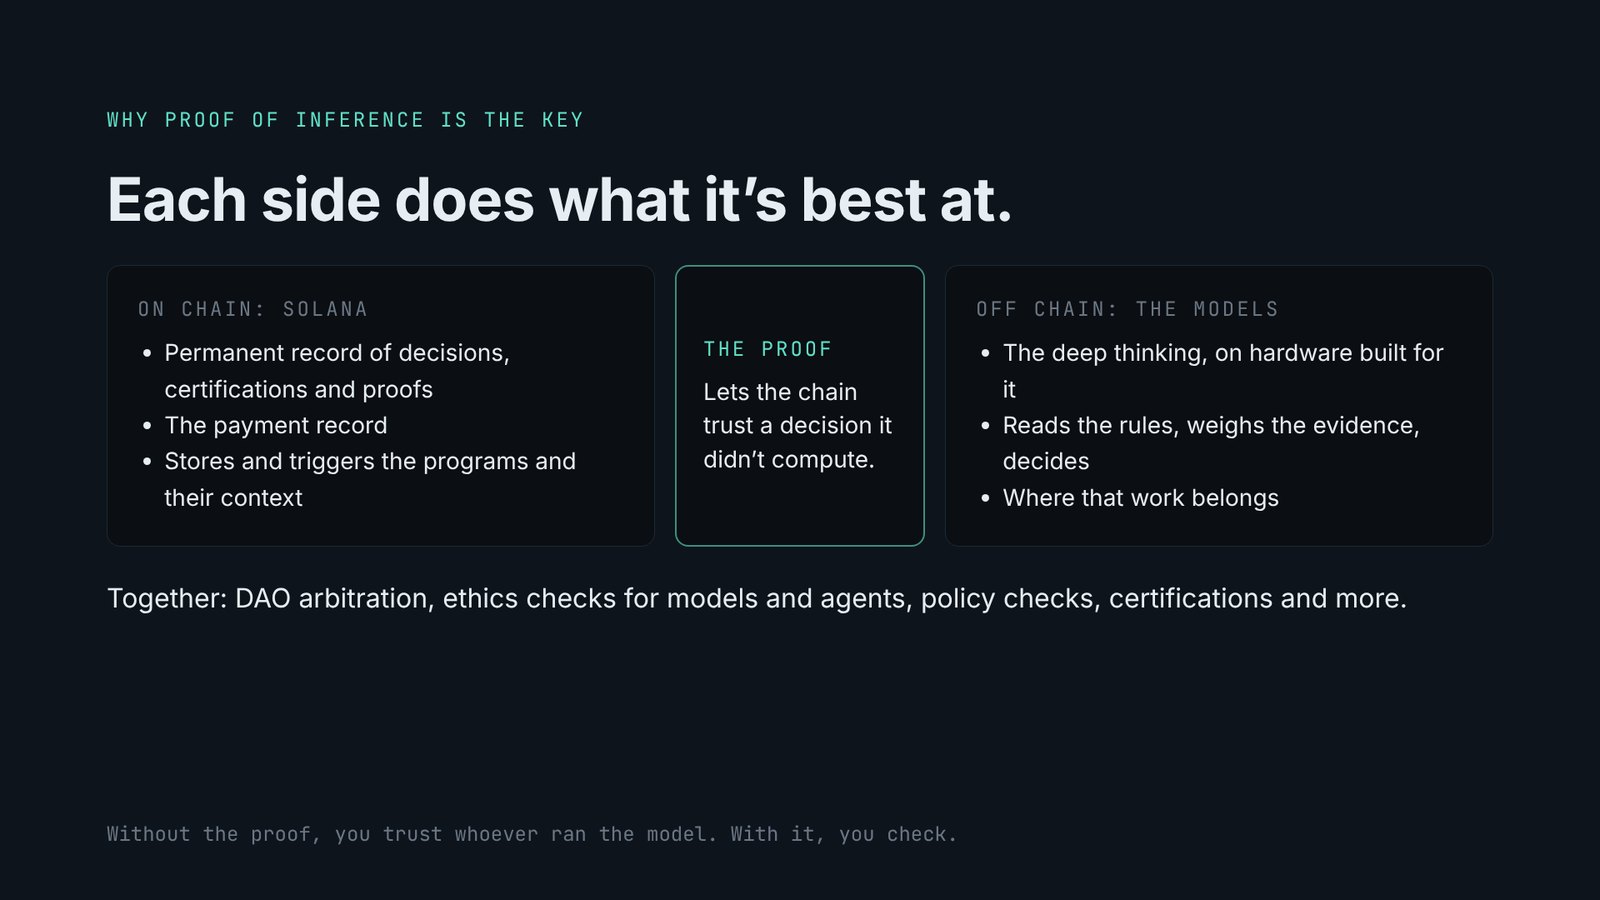
Proof of inference lets each side do what it’s best at.
Solana does what blockchains do best. It keeps a permanent, public record of decisions, certifications and proof statements, and of every payment. It stores the programs and the context the models should use, and it lets other programs trigger them.
Models do the deep thinking, off chain. Reading a constitution, weighing evidence and deciding whether an action breaks a rule takes large models on serious hardware. That work doesn’t belong on chain, and it doesn’t need to be there.
The proof joins them. It shows which model gave the answer, so the chain can trust a decision it didn’t compute. Without it, you’re trusting whoever ran the model. With it, you’re checking.
Together, that opens up a wide range of uses: DAO arbitration, ethics checks for AI models and agents, policy checks, certifications, and more.
Why now
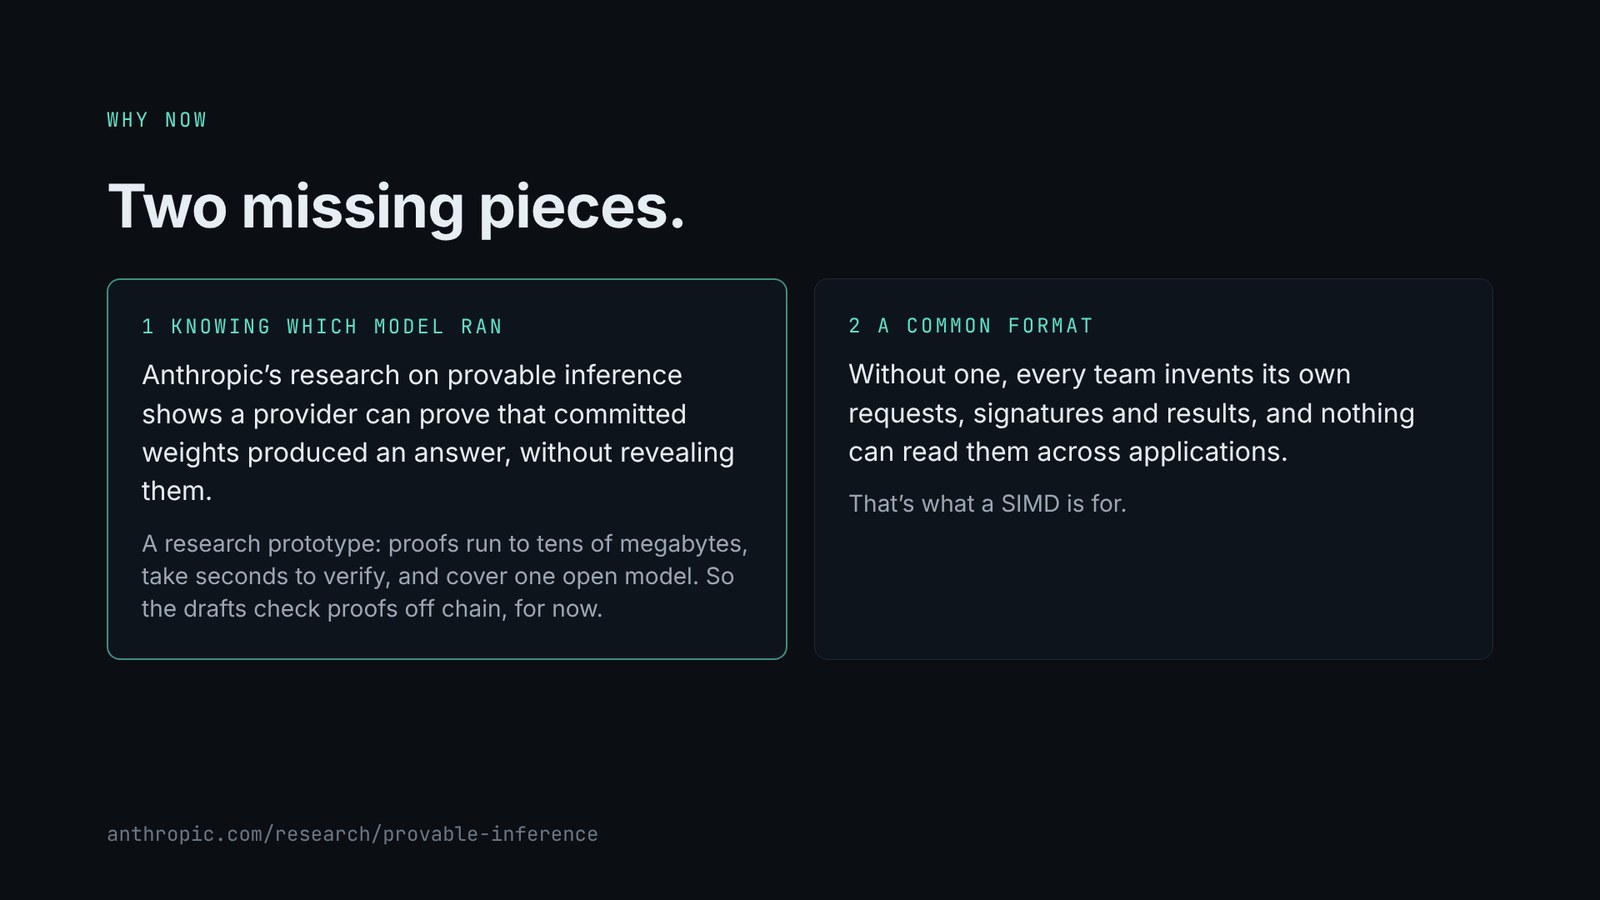
Two pieces have been missing.
The first is a way to know which model ran. A signature proves which key signed, not which model did the work. Anthropic’s research on provable inference shows that a provider can prove a committed set of model weights produced a specific answer, without revealing the weights. It’s a research prototype today: proofs run to tens of megabytes and take seconds to verify, for one open model. That’s too large to check inside a Solana transaction, so the drafts verify proofs off chain and leaves room to bring verification on chain later.
The second is a common format. Without one, every team invents its own requests, signatures and results, and nothing can read them across applications. That’s what a SIMD is for.
What it would make possible
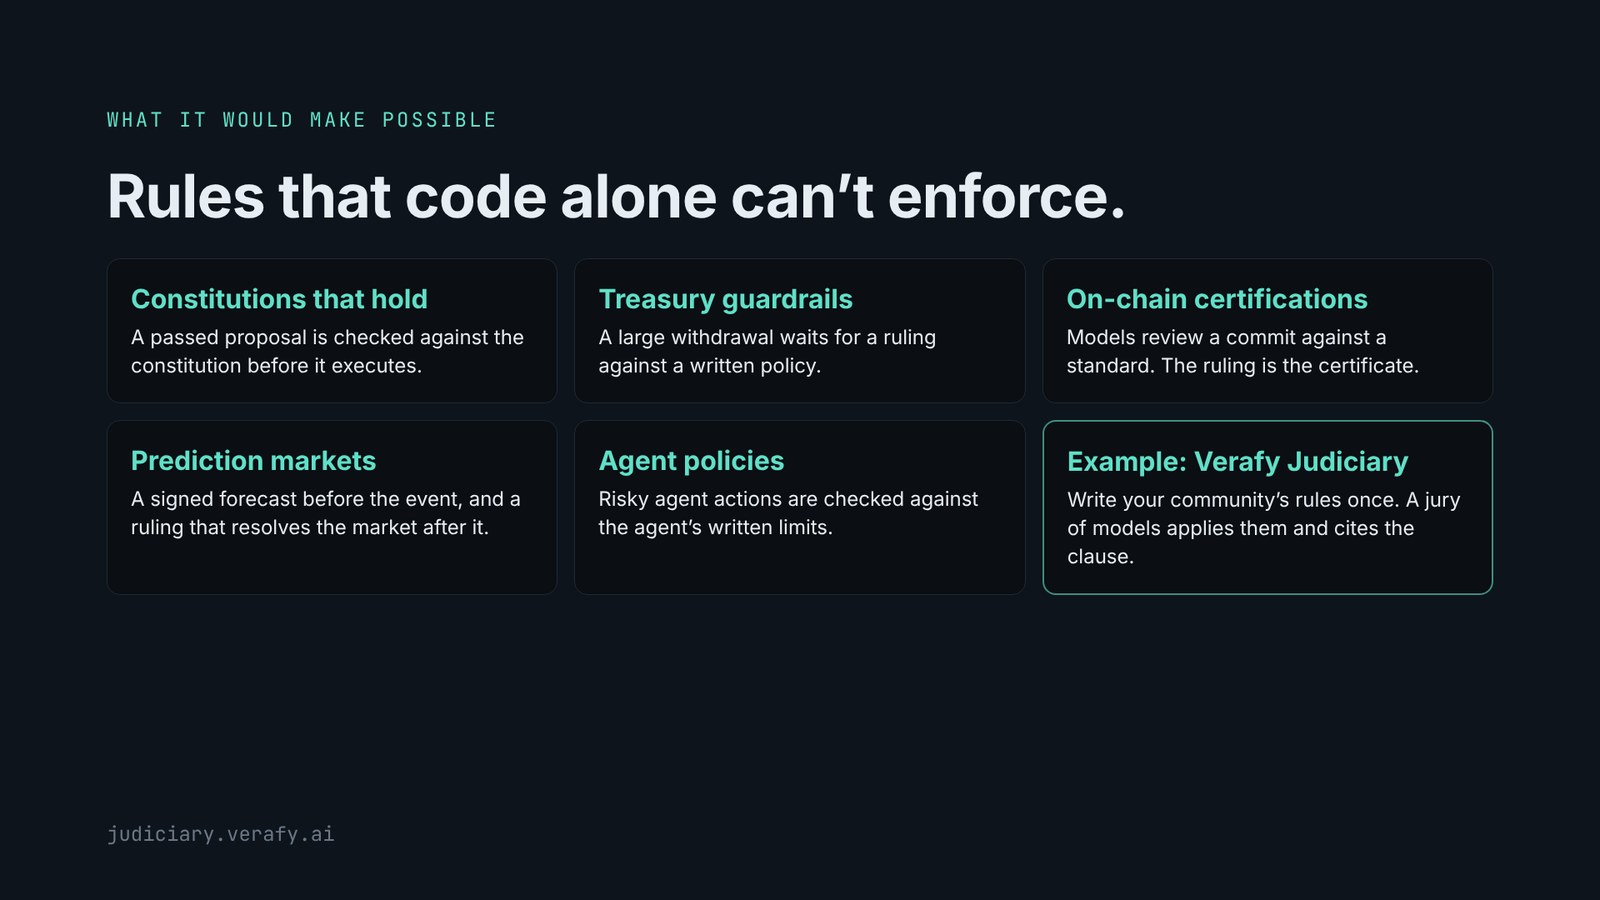
- Constitutions that hold. A DAO checks a passed proposal against its inscribed constitution before it executes.
- Treasury guardrails. A withdrawal over a threshold waits for a ruling against a written policy.
- On-chain certifications. A published standard, like “a consumer device shall never record without a visible indicator,” becomes a program. Models review a specific commit against it, and the ruling is a public certificate.
- Judgment clauses. Grants and escrow that pay when what was promised actually happened.
- Agent policies. Programs acting for AI agents check risky actions against the agent’s written limits.
For an example of what we have in mind, see Verafy Judiciary. You write your community’s rules once, and a jury of AI models from different companies applies them to a dispute and cites the clause behind each ruling. These SIMDs are how rulings like that could be recorded on chain, proven, and acted on by any Solana program.
What’s in the drafts
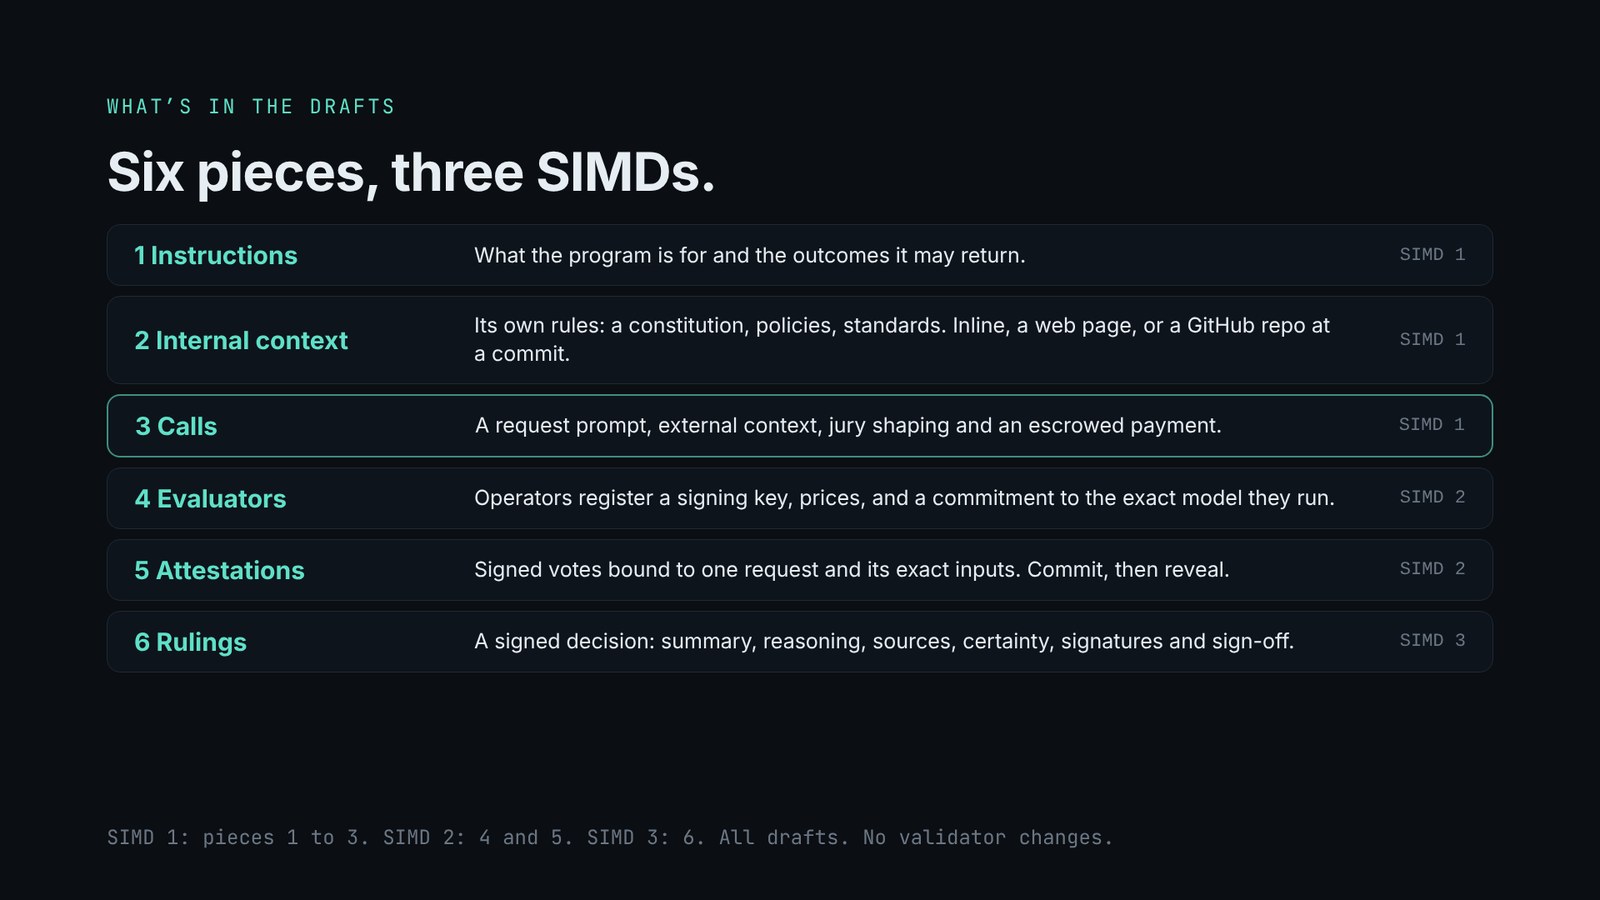
Across the three drafts there are six pieces. Inference Programs covers the first three, Evaluators and Attestations the next two, and Rulings, Disputes and Challenges the last.
- Instructions. What the inference program is for and the outcomes it may return, stored on chain in whatever form is smallest or most private.
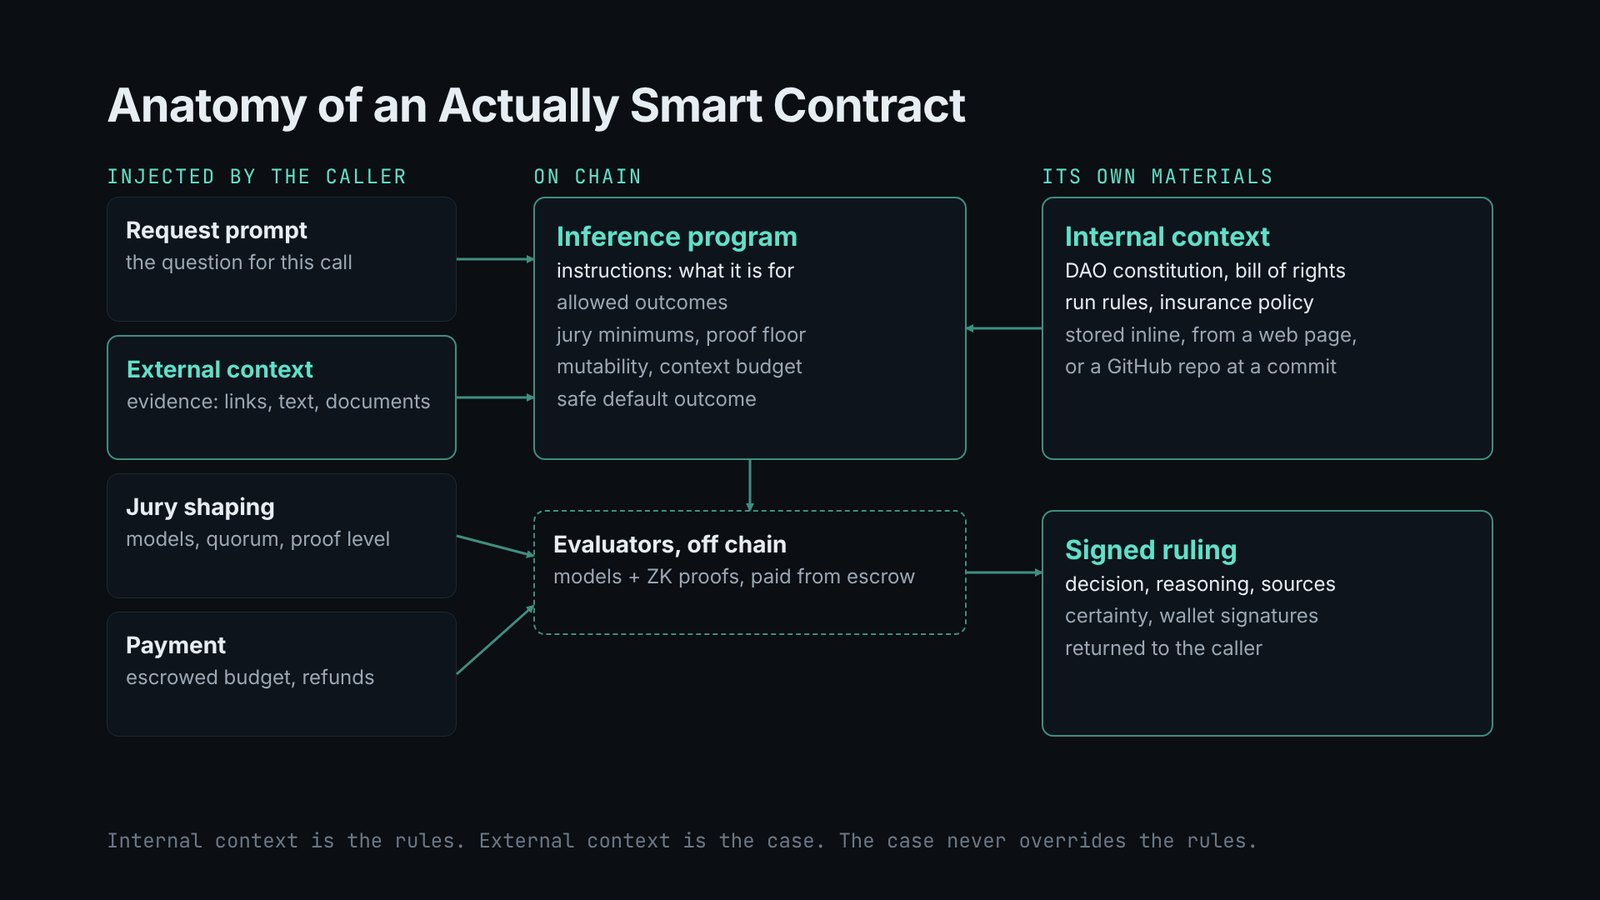
- Internal context. The program’s own materials, which apply to every call: a DAO constitution or bill of rights, run rules, an insurance policy, certification standards. They can be stored inline, pulled from a web page, or pulled from a trusted GitHub repository pinned at a commit. It loads into the model’s context window with the prompt, so one call can run a policy check, a legal check, a tax check, an insurance check or a DAO rules check.
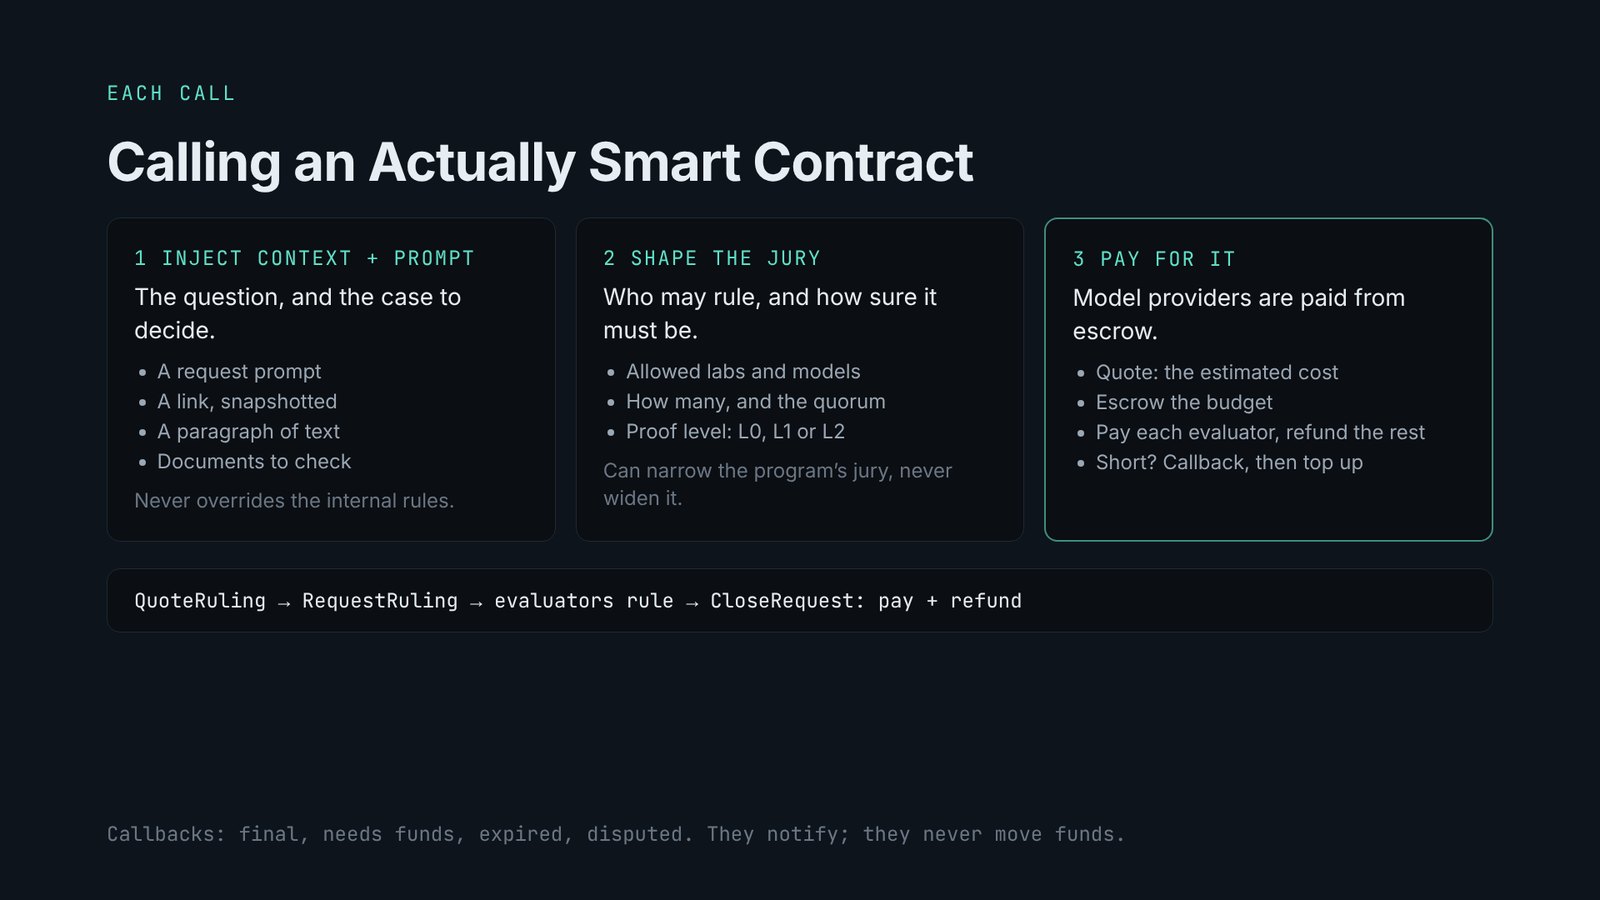
- Calls. Each call injects a request prompt (the question), external context (the evidence: a link, a paragraph, documents to check), jury shaping (which labs and models, how many, what level of proof) and payment. The caller gets a cost estimate first, escrows a budget that pays the model providers, is refunded what’s left, and gets a callback to add funds if it runs short. External context never overrides internal context.
- Evaluators. Model operators register a signing key and a commitment to exactly what they run: hashes of the weights, the tokenizer and the decoding settings.
- Attestations. One exact message format for the signature, bound to one request, its instructions, its internal and external context, and its input. Votes are committed before they’re revealed, and checked with Solana’s existing Ed25519 verification.
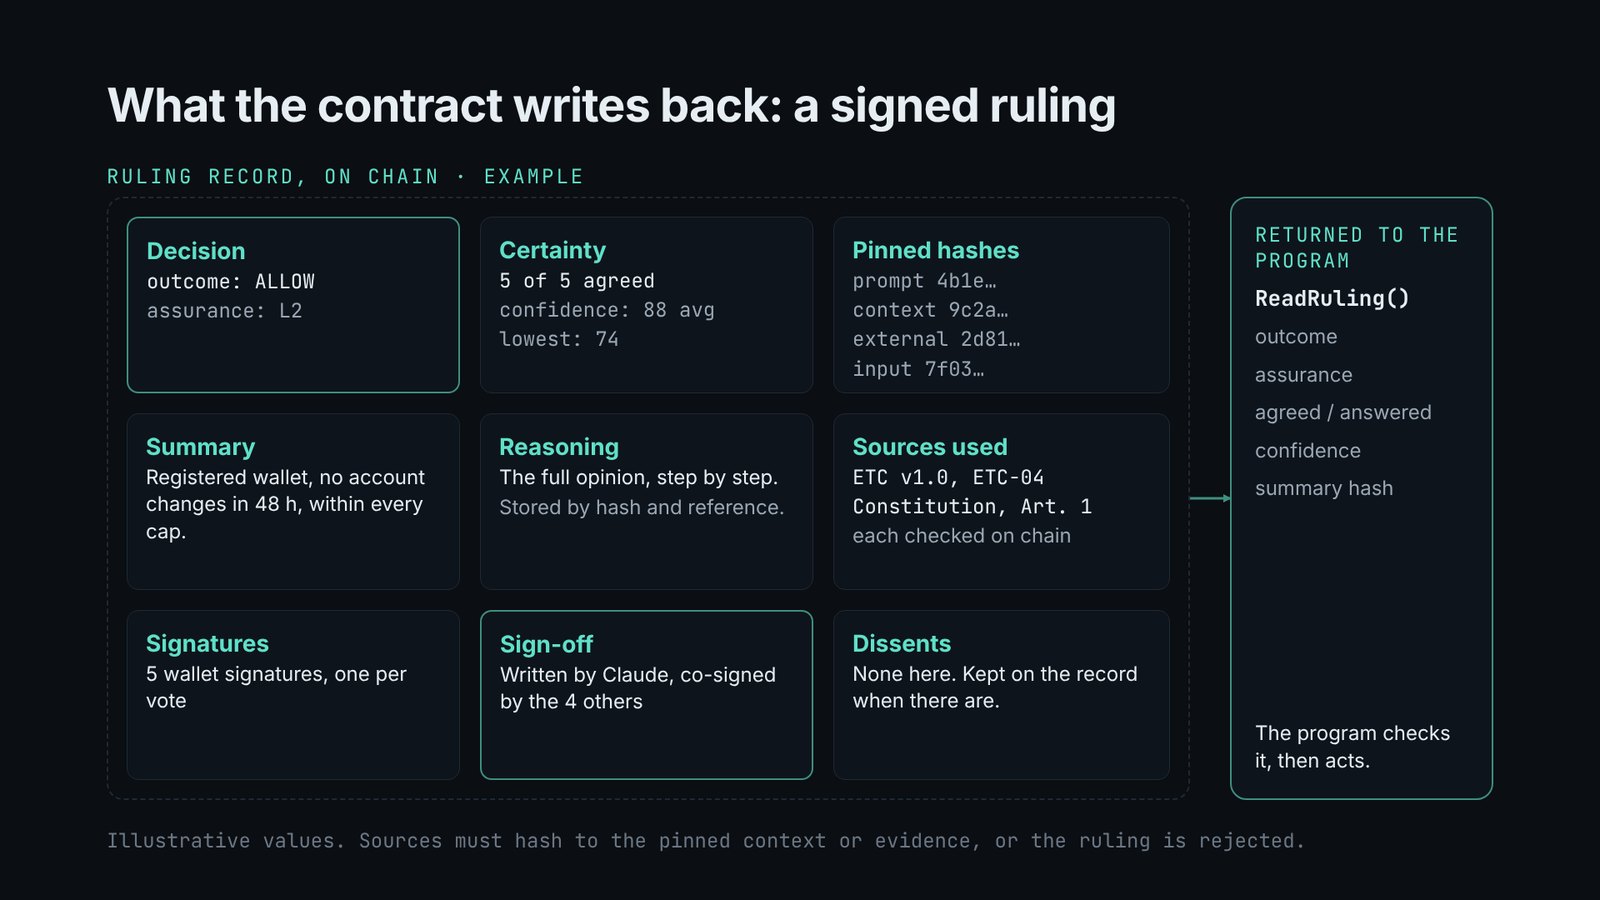
- Rulings. The contract writes back a signed decision, like a court opinion: the outcome, a short summary, the full reasoning, the sources it relied on (each checked against the internal and external context it was given), how strongly the models agreed, every model’s wallet signature, and a sign-off where one model writes the opinion and the others co-sign it. Dissents stay on the record. Quorum, a safe default, disputes and three assurance levels come with it.
Small, private and changeable
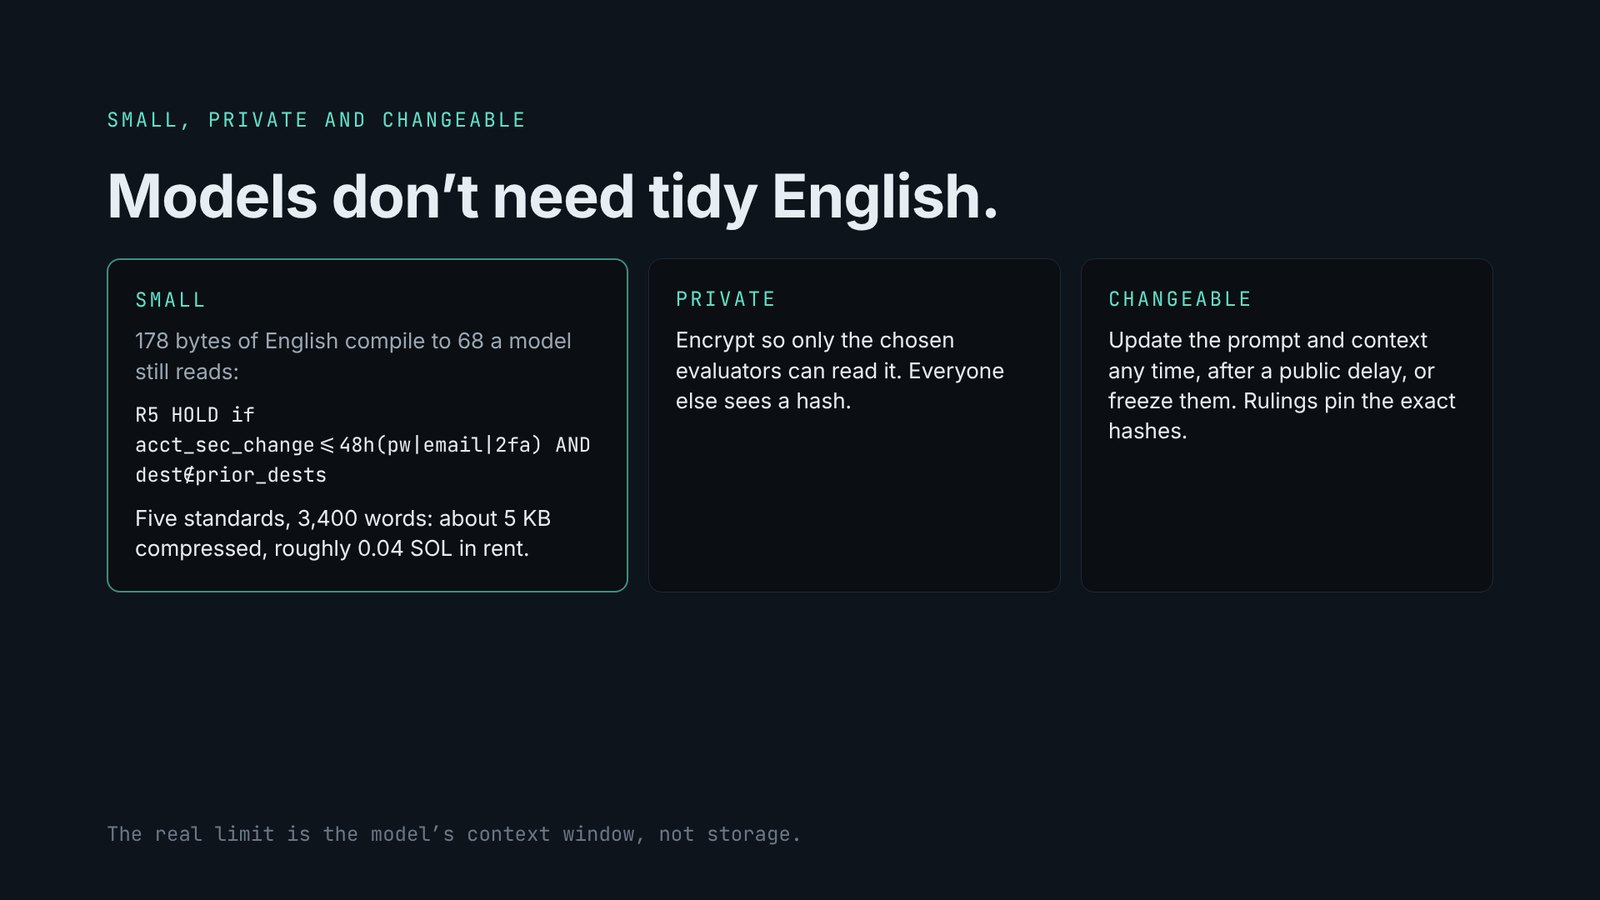
Models don’t need tidy English. A prompt can be written in any language and compiled into a terse form a model still reads directly. One of our 178-byte withdrawal rules compiles to 68 bytes:
R5 HOLD if acct_sec_change<=48h(pw|email|2fa) AND dest∉prior_dests
On top of that, content can be compressed, and encrypted so that only the chosen evaluators can read it. Everyone else sees a hash. Evaluators decompress and decrypt before the model sees anything.
Context can also be a link: a DAO forum thread, a governance proposal, a web page. Live pages change, so a link is captured once into a snapshot with its hash, and every model rules on that same snapshot. To rule on a newer version, take a new snapshot.
Storage is cheap. Our five draft standards, about 3,400 words together, compress to about 5 KB, which costs roughly 0.04 SOL in rent at today’s rates. A single account holds up to 10 MiB. The real limit is the model’s context window, so every program declares a context budget and evaluators declare what they can take.
And both the prompt and its context can change. Whoever creates the program can update them at any time, stage changes behind a public delay, or freeze them for good. Every ruling pins the exact hashes it used, so a change never rewrites a past decision.
Rulings can be challenged and overturned
A ruling isn't the last word, and it shouldn't be. Evidence turns out to be forged, a source is corrected, or the reasoning looks wrong once more is known. Courts deal with this by letting a later court overturn an earlier decision, sometimes generations later, while the original stays in the record. Inference programs work the same way.
There are two kinds of review. A dispute is quick: within a short window, a fresh ruling is re-judged on the same evidence by different model families, before anyone relies on it. A challenge can come at any time, with no deadline. The challenger names the grounds (new evidence, false evidence, misapplied rules, or rules that have since changed), posts a bond and pays for the review. The challenge jury gets the original ruling and its full reasoning, the original evidence, and the new material, clearly labeled as new. It has to compare itself to the original, source by source, and say which new source changed the answer.
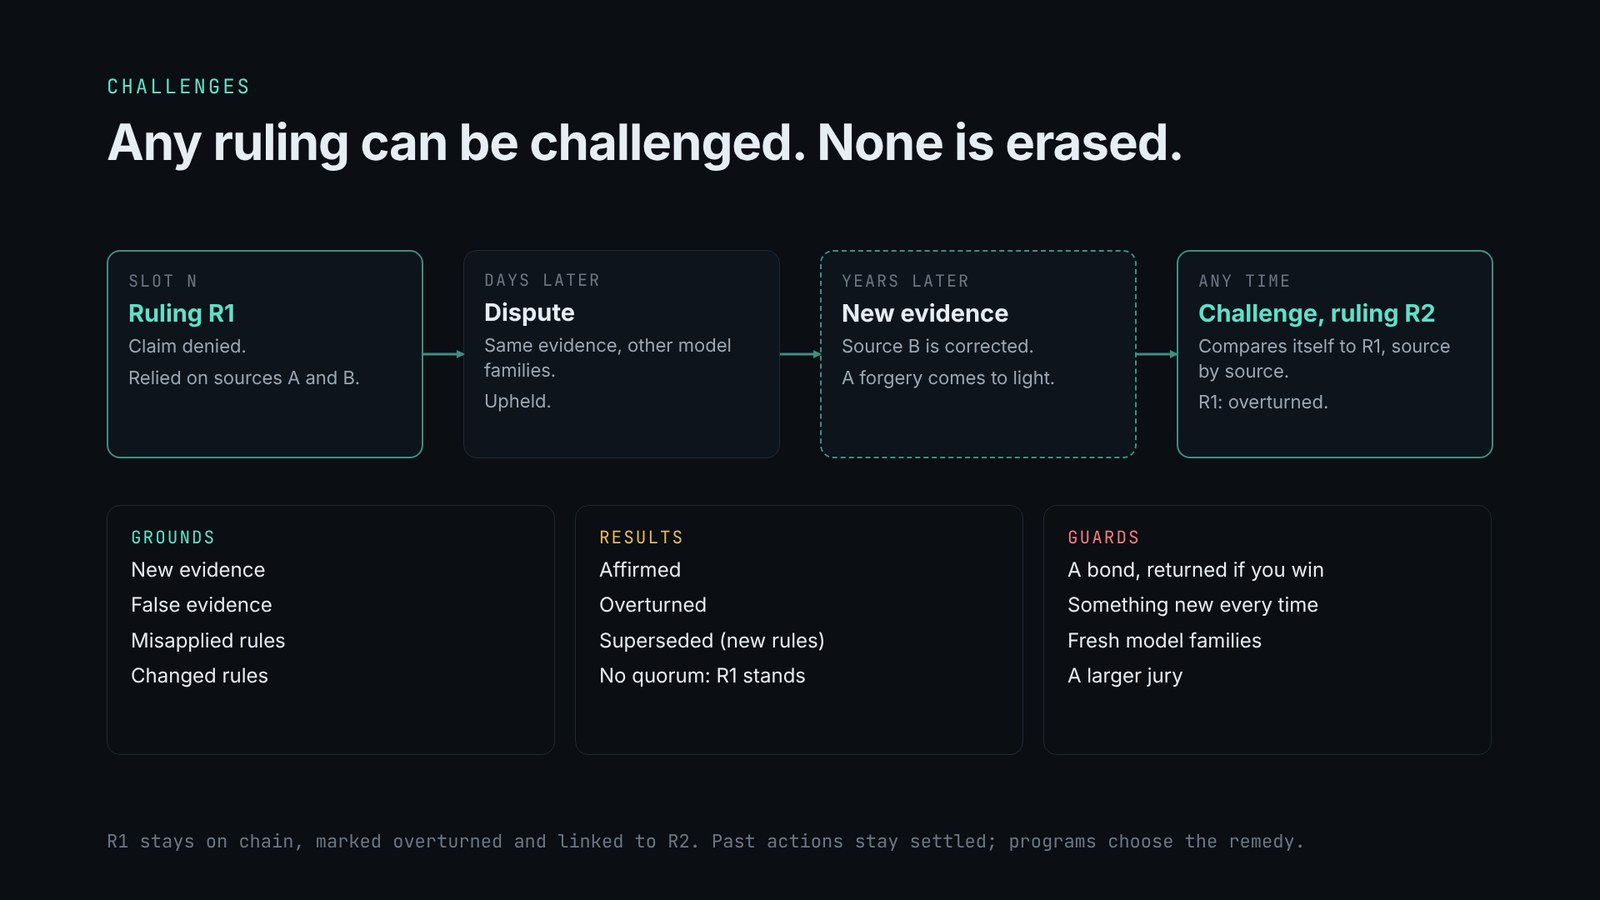
The result is affirmed, overturned, or superseded when the rules themselves changed. Nothing is erased: the original stays on chain, marked overturned, with a link to the ruling that overturned it, so the whole history can be read back. Past actions stay settled. What changes is the record and what programs do next. An insurer can pay a claim whose denial was overturned, and no program may act on an overturned ruling. To stop a losing side from relitigating until it draws a friendlier jury, every challenge must bring something no earlier review considered, the bond is returned only if the challenge wins, and each review uses fresh model families. Past rulings can also be cited as precedent in a program's context, always with their review status attached.
Faster and cheaper: System 1 models
A ruling from a jury of language models takes 20 to 60 seconds in our recorded runs. That's fine for a DAO proposal and too slow for an agent's loop or a busy withdrawal queue. A new kind of model may help. TypeSafe's Jev is what they call a System One model: instead of writing text, it returns a typed answer (a choice, a score, or a yes or no) with a calibrated probability, in 70 to 500 milliseconds and for about $0.0004 a decision, by the vendor's own figures.
The names come from psychology: System 1 is the fast gut check, System 2 is slow, careful reasoning. In an inference program, System 1 screens and System 2 rules. Each rule in the program's internal context becomes one yes or no question, checked in parallel. A clear, low-stakes case gets a fast result or the safe default. An unclear or costly one escalates to the full jury, and the screen's probability can decide how big that jury should be.
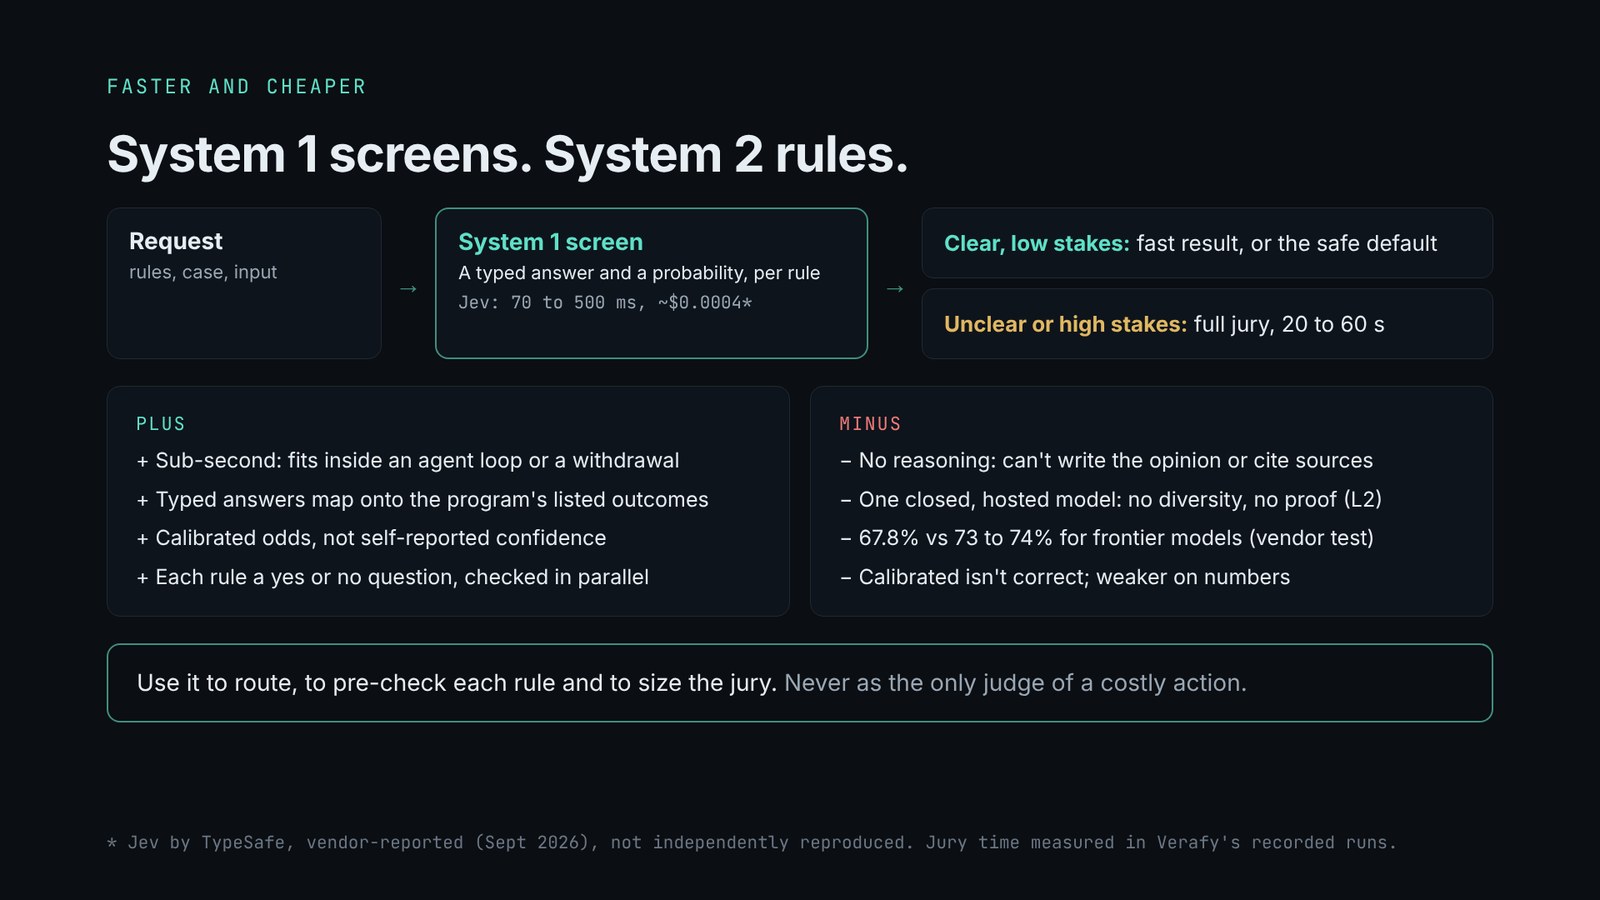
The pluses are real. It's sub-second, so it fits where a jury can't. Its typed answers map straight onto the outcomes a program lists. Its probabilities are trained to be calibrated, which beats a language model reporting how confident it feels. The minuses matter as much. It writes no reasoning, so it can't produce the opinion, summary and sources a ruling needs. It's one hosted, closed model, so it adds no diversity of labs and can't carry a proof of inference. On TypeSafe's own benchmark it scored 67.8% against 73 to 74% for frontier models, and calibrated isn't the same as correct. So it's the fast lane, not the court: the attestations draft adds an informative section on using System 1 models as a screen, as an evaluator that votes but doesn't write the opinion, and to size the jury.
What it doesn’t do
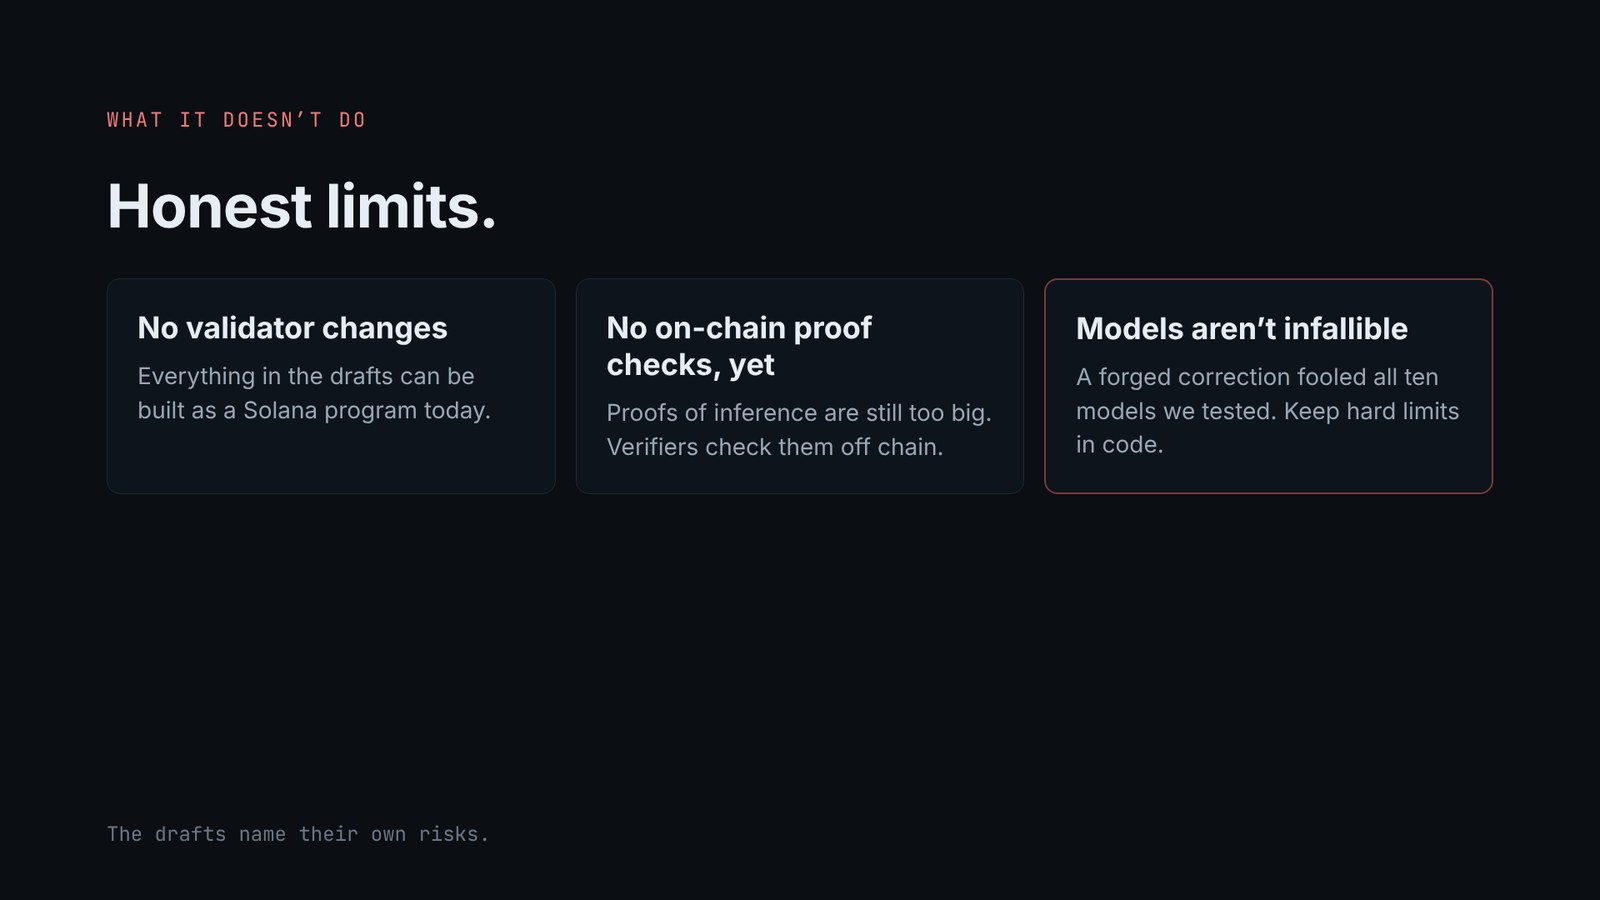
It doesn’t change the validator. Everything in the drafts can be built as a Solana program today. It doesn’t verify proofs of inference on chain, because they’re still too big. And it doesn’t make models infallible: in our tests, a forged correction in the evidence fooled all ten models we tried. The drafts say so, and ask calling programs to keep hard limits in their own code.
Next step
Solana’s SIMD process asks that ideas be discussed before a proposal is submitted. We’re opening a discussion in the SIMD repository’s Ideas section to find out whether this is viable, what’s wrong with it, and who wants to build it with us. All three drafts are below.
See Actually Smart Contracts run.
SIMD 1 (draft): Inference Programs
simd: 'XXXX'
title: Inference Programs
authors:
  - Rex St. John (Verafy)
category: Standard
type: Interface
status: Idea
created: 2026-11-05
feature: (fill in with feature key and github tracking issues once accepted)
Summary
These SIMDs are part of a broader proposal to bring Inference Programs to Solana natively: Bringing Inference Programs To Solana.
This proposal defines inference programs: programs written in natural language, stored on chain, called by other Solana programs, and executed off chain by AI models. It standardizes how a program's prompt and context are stored (inline, from a web page or a git repository at a commit, compact, compressed or encrypted), how they change over time, and how a caller requests a ruling: with a request prompt, external context, a jury specification, and an escrowed budget that pays the model operators and refunds the rest.
This is one of three companion proposals that bring inference programs to Solana:
- Inference Programs: natural-language programs on chain, their context, and how other programs call and pay for them.
- Inference Evaluators and Attestations: who runs the models, what they commit to, and the signed, optionally provable, vote each one casts.
- Inference Rulings, Disputes and Challenges: how votes become a signed ruling that programs act on, and how rulings are disputed, challenged and overturned.
The motivation, use cases and diagrams for all three are in the overview post.
Motivation
A smart contract can enforce only what code can express: balances, signatures, timestamps and arithmetic. Many rules that matter most to on-chain organizations are judgments: "the treasury shall not fund political campaigns", "what a proposal does must match what its text says", "hold any withdrawal that looks like an account takeover". Today they live in forum posts and constitutions that nothing on chain can check, and judgment happens off chain, by a multisig or a vote.
Large language models can read and apply rules like these. To use them from a smart contract, the rules need a public, versioned home on chain, every ruling must name the exact text it applied, and calling programs need one way to ask, pay and read back. This proposal provides the first two and the request side of the third.
Dependencies
This proposal depends on the following proposals, submitted together:
-
SIMD-XXXX: Inference Evaluators and Attestations
Defines the evaluators that serve a request, and the JurySpec fields that refer to them.
-
SIMD-XXXX: Inference Rulings, Disputes and Challenges
Defines the Ruling that answers a request, and uses the request
kindandreviewsfields.
New Terminology
-
Inference program: An on-chain account that names a prompt, a context set, an output schema and evaluation requirements.
-
Prompt: The instructions the model follows, with the list of allowed outcomes.
-
Context set: An ordered list of context documents (policies, rules, a constitution, standards, contract terms, or linked pages such as a DAO discussion) that evaluators load into the model's context alongside the prompt.
-
Internal context: The inference program's own materials, which apply to every request: a DAO constitution or bill of rights, run rules, an insurance policy, standards. Stored inline, or pulled from a web page or a trusted GitHub repository pinned at a commit.
-
External context: Context a caller injects into one request: the evidence and case being decided, as links, text or documents. It never overrides internal context.
-
Request prompt: The caller's question for one request, such as "Does proposal 42 comply?". It works within the program's instructions and cannot add outcomes.
-
Jury specification: The part of a request that says who may rule: how many evaluators, the quorum, the required assurance level, and which model families or specific models are allowed.
-
Budget: Lamports a requester escrows to pay evaluators and verifiers. Unspent budget is refunded.
-
Linked content: A context document or evidence item given as a URL. It is fetched once into a snapshot, and every evaluator reads the same snapshot.
-
Content account: An account that holds one prompt or one context document, in any supported encoding, inline or by external reference.
-
Encoding: How stored bytes become model input: plain text, a compact compiled form, compressed, encrypted, or a combination.
-
Context budget: The number of tokens an evaluator must be able to accept for the prompt, context and input together.
-
Revision: A counter that increases every time a prompt or context set changes.
-
Mutability mode: Whether a creator can change content immediately (mutable), only after a public delay (timelocked), or never (frozen).
-
Ruling request: An account recording a request to run one inference program on one input, with the pinned prompt and context hashes, quorum and deadlines.
Detailed Design
The key words "MUST", "MUST NOT", "REQUIRED", "SHALL", "SHALL NOT", "SHOULD", "SHOULD NOT", "RECOMMENDED", "NOT RECOMMENDED", "MAY", and "OPTIONAL" in this document are to be interpreted as described in RFC 2119 and RFC 8174.
All integers are little-endian. All hashes are SHA-256 unless stated
otherwise. Account layouts begin with an 8-byte discriminator equal to the
first 8 bytes of sha256("inference-programs:" || account_name).
Accounts
InferenceProgram
discriminator        [u8; 8]
authority            Option<Pubkey>  // None once frozen
mutability           u8         // 0 mutable, 1 timelocked, 2 frozen
update_timelock      u64        // slots, used when mutability = 1
revision             u32        // +1 on every prompt or context change
prompt               Pubkey     // Content account holding the prompt
context_set           Option<Pubkey>  // ContextSet account
pending_prompt       Option<Pubkey>  // staged change, timelocked mode
pending_context_set   Option<Pubkey>  // staged change, timelocked mode
pending_after        u64        // slot after which staged changes apply
context_budget       u32        // tokens evaluators must accept
ext_context_mode     u8         // 0 not accepted, 1 optional, 2 required
ext_context_kinds    u16        // bit per ContextEntry kind a caller may add
ext_context_budget   u32        // tokens of external context allowed
min_evaluators       u8         // floor on evaluators per request
min_quorum           u8         // floor on agreeing attestations
min_assurance        u8         // 0, 1 or 2
distinct_families    bool       // require distinct model families
default_outcome      u8         // outcome on expiry or no quorum
evaluator_set        Option<Pubkey>  // optional EvaluatorSet account
name                 [u8; 64]   // UTF-8, zero padded
Content
Holds one prompt or one context document.
discriminator        [u8; 8]
authority            Option<Pubkey>
revision             u32
content_hash         [u8; 32]   // sha256 of the stored bytes
source_hash          [u8; 32]   // sha256 of the plain-text source, or zero
encoding             u8         // bit flags, see "Encodings"
stored_len           u32        // bytes held here or externally
decoded_len          u32        // bytes after decryption and decompression
token_estimate       u32        // creator's estimate of model tokens
storage_kind         u8         // 0 inline, 1 external, 2 link,
                                // 3 git repository
external_ref         [u8; 96]   // e.g. an inscription's transaction
                                // signature, zero padded
link                 [u8; 256]  // URL when storage_kind is 2 or 3
git_commit           [u8; 20]   // pinned commit when storage_kind = 3
git_path             [u8; 128]  // file or folder in the repository
snapshot_slot        u64        // when the linked page was captured
key_envelope         Option<Pubkey>  // KeyEnvelope account, if encrypted
outcome_count        u8         // prompts only
outcomes_hash        [u8; 32]   // prompts only: sha256 of outcome list
writing              bool       // true while chunks are being written
updated_slot         u64
content              [u8]       // inline bytes when storage_kind = 0
Content larger than one transaction is written in chunks with
WriteContentChunk while writing is true. SealContent MUST check that the
sha256 of the bytes equals content_hash and sets writing to false.
Evaluators MUST NOT use content while writing is true.
With storage_kind = 1, the bytes live elsewhere (for example, an inscription
stored by another program, or a content-addressed store) and only the hash is
held here. Evaluators MUST fetch the bytes, check that their sha256 equals
content_hash, and refuse to attest otherwise.
Linked content. With storage_kind = 2, the content is a page on the
web, such as a DAO forum thread, a governance proposal, a news article or a
terms-of-service page. Live pages change, and evaluators fetching them at
different moments would rule on different text. So a link is always ruled on
through a snapshot:
SnapshotLinkrecords the sha256 of the captured page incontent_hash, a reference to the stored copy inexternal_ref, andsnapshot_slot. Any signer may capture a link that has no snapshot yet. A program MAY limit capture to its authority or to listed evaluators.- Requests pin the snapshot's
content_hash, like any other content. Evaluators MUST read the snapshot, not the live page, and MUST refuse to attest if it does not match the hash. - To rule on a newer version of the page, take a new snapshot. That changes the context hash, so it is a new revision.
Git repositories. With storage_kind = 3, the content is a file or
folder in a git repository the creator trusts to publish its rules, pinned
at git_commit. content_hash is the sha256 of the files at that commit, in
sorted path order. Moving to a newer commit is an update like any other, so
it follows the program's mutability mode.
Snapshots SHOULD store the page as text with its URL, title and capture time,
and SHOULD strip scripts and markup. Requests can also carry links as
evidence: the requester snapshots each linked page, and evidence_hash
covers the snapshot hashes.
ContextSet
discriminator        [u8; 8]
authority            Option<Pubkey>
revision             u32
context_hash         [u8; 32]   // sha256 over the ordered list of
                                // (kind, label, content_hash) entries
count                u8
entries              [ContextEntry; count]

ContextEntry:
  content            Pubkey     // Content account
  content_hash       [u8; 32]   // must equal that account's content_hash
  kind               u8         // 0 constitution, 1 standard, 2 regulation,
                                // 3 contract terms, 4 internal policy,
                                // 5 rules, 6 discussion, 7 web page,
                                // 8 other shaping context,
                                // 9 prior ruling (see Rulings)
  label              [u8; 32]   // e.g. "EDO v1.0", zero padded
A context set lets one inference program apply several rule sets at once. For example, a certification program can hold its standards (EDO v1.0 and EAO v1.0) as two entries, and a treasury program can hold the DAO constitution and the treasury policy. Context sets MAY be shared by many inference programs.
Evaluators MUST place the context documents in the model's context in entry
order, before the prompt and the input, each preceded by its kind and
label. The prompt SHOULD instruct the model to cite the context entry and
section behind each finding.
KeyEnvelope (encrypted content only)
discriminator        [u8; 8]
content              Pubkey
scheme               u8         // 0 = X25519 + HKDF-SHA256 + ChaCha20-Poly1305
count                u8
wraps                [KeyWrap; count]

KeyWrap:
  evaluator          Pubkey     // Evaluator account
  ephemeral_pub      [u8; 32]
  wrapped_key        [u8; 48]   // content key encrypted to the evaluator
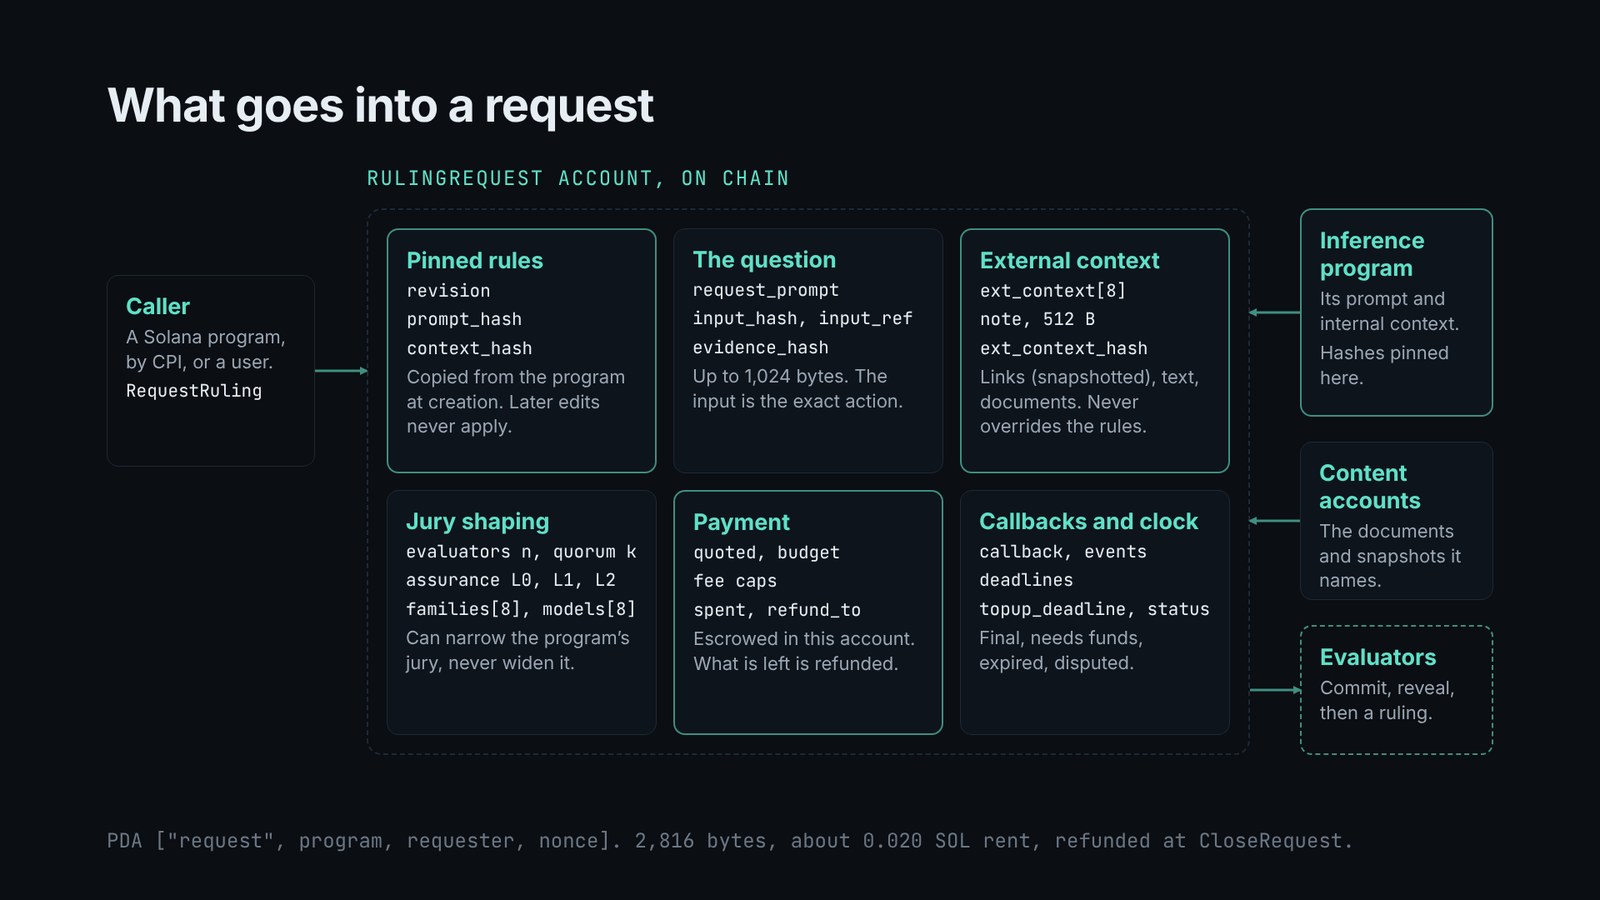
RulingRequest
A PDA at ["request", inference_program, requester, nonce_le_u64].
discriminator        [u8; 8]
inference_program    Pubkey
revision             u32        // pinned at creation
prompt_hash          [u8; 32]   // pinned prompt content_hash
context_hash         [u8; 32]   // pinned context_hash, or zero
requester            Pubkey
input_hash           [u8; 32]   // sha256 of the canonical input
input_ref            [u8; 96]   // where evaluators fetch the input
evidence_hash        [u8; 32]   // sha256 over sorted evidence hashes,
                                // or zero
ext_context_hash     [u8; 32]   // sha256 over the external context, or zero
ext_context_count    u8
ext_context          [ContextEntry; 8]  // caller-supplied documents
request_prompt_len   u16
request_prompt       [u8; 1024] // the caller's question, UTF-8
jury                 JurySpec
max_input_tokens     u32        // cap used for pricing and context checks
max_output_tokens    u32
budget               u64        // lamports escrowed in this account
quoted               u64        // estimate from QuoteRuling at request time
spent                u64        // paid out so far
refund_to            Pubkey     // receives what is left
callback_program     Option<Pubkey>  // notified of the events below
callback_events      u8         // bits: final, needs funds, expired,
                                // disputed
topup_deadline       u64        // slot by which a shortfall must be covered
commit_deadline      u64        // slot
reveal_deadline      u64        // slot
opinion_window       u64        // slots for the rapporteur to post
signoff_deadline     u64        // slot by which sign-offs must land
dispute_window       u64        // slots after finalization
kind                 u8         // 0 ruling, 1 dispute, 2 challenge
reviews              Option<Pubkey>  // the Ruling under review, if any
status               u8         // 0 open, 1 revealing, 2 final,
                                // 3 disputed, 4 expired, 5 closed,
                                // 6 needs funds

JurySpec:
  evaluators         u8         // number of attestations sought (n)
  quorum             u8         // agreeing attestations required (k)
  assurance          u8         // 0 signatures, 1 diverse, 2 proven
  distinct_families  bool
  family_count       u8
  allowed_families   [[u8; 32]; 8]  // empty = any family
  model_count        u8
  allowed_models     [Pubkey; 8]    // ModelCommitment accounts,
                                    // empty = any model
  max_fee_each       u64        // most any one evaluator may be paid
  verifier_fee       u64        // per proof verification, for L2
RequestRuling MUST set the jury's evaluators, quorum and assurance to
at least the inference program's minimums, MUST NOT allow a model or family
outside the program's evaluator set when it has one (a request can narrow
the jury, never widen it), and MUST copy revision, prompt_hash and
context_hash from the program as it stands at that slot. A request MAY
instead name an earlier revision's hashes, if that content is still
retrievable.
Encodings
Models do not need prompts in tidy English. A prompt or context document can
be stored in whatever form is smallest or most private, as long as evaluators
can turn it into model input. encoding is a set of bit flags, applied in
this order when writing and reversed when reading:
-
Bit 0, compact. A compiled, terse form of the source that a model reads directly: abbreviations, symbols and structured shorthand instead of full sentences. The source can be written in any human language. For example, this 178-byte rule:
Hold the withdrawal if it looks like an account takeover: a password, email or 2FA change in the last 48 hours, followed by a withdrawal to an address the account has never used.
compiles to 68 bytes:
R5 HOLD if acct_sec_change<=48h(pw|email|2fa) AND dest∉prior_destsCompact content MUST carry a non-zero
source_hash, so anyone holding the plain source can check which text it was compiled from. Creators SHOULD test that the compact form produces the same rulings as the source on a set of sample inputs, because compilation can change meaning. -
Bit 1, compressed. zstd. Evaluators MUST decompress before building model input. Models do not read compressed bytes directly.
-
Bit 2, encrypted. ChaCha20-Poly1305 under a random content key, wrapped to each listed evaluator's X25519 key in a KeyEnvelope. Only those evaluators can read the content. Everyone else sees the hash, the length and the token estimate. Evaluators MUST decrypt before building model input.
content_hash always covers the stored bytes, so the chain can check that
nothing changed. source_hash covers the human-readable source, so a creator
can later publish the source and prove it is what the models ran.
Storage size and cost (informative)
Content accounts can hold up to 10 MiB. Larger content is written in chunks. At
current parameters a rent-exempt account costs 6,960 lamports per byte plus a
128-byte header, refunded when it is closed. Five certification standards
together (22,712 bytes of text) compress to 5,246 bytes, about 0.0377 SOL of
rent; measurements for other texts are in the overview
post. In
practice the limit is the evaluator's context, not storage: the prompt, all
context and the input must fit within context_budget. Creators SHOULD set
token_estimate on every content account.
Mutability
Creators can change both the prompt and the context set. How fast depends on
mutability:
- Mutable (0).
SetPrompt,SetContextSetandUpdateContenttake effect in the slot they land, andrevisionincreases. - Timelocked (1). Changes are staged in
pending_promptandpending_context_setand apply only afterpending_after, which is the staging slot plusupdate_timelock. Anyone can see a change coming. - Frozen (2). Nothing changes again.
authorityisNone.
SetMutability MUST only move toward frozen: mutable to timelocked, or either
to frozen.
Every change MUST emit a log line with the old and new content_hash or
context_hash, so indexers can keep a history. Implementations SHOULD store
each revision's bytes somewhere retrievable, such as an inscription, so any
past ruling can be checked against the exact text it applied.
Requests are never affected by later changes. A request pins prompt_hash and
context_hash at creation, and evaluators MUST attest against the pinned
content. If the creator replaces the content before evaluators fetch it and
the old bytes are not retrievable, evaluators cannot attest and the request
expires to default_outcome.
External context
Internal context is set by the inference program's creator and applies to every request. External context is supplied by whoever calls the program and applies to one request. A DAO's constitution is internal context; the proposal being judged, its forum thread and its decoded calldata are call context. An insurer's policy terms are internal context; a claim and its photos are external context.
RequestRuling accepts up to 8 external-context entries, each a Content account
(inline, external or a snapshotted link), plus a short inline note of up to
512 bytes. A calling program can inject context through cross-program
invocation by creating Content accounts for longer material, or by passing
the note in instruction data. The program MUST check:
ext_context_modeallows external context, and requires it when set to 2.- Every entry's
kindis allowed byext_context_kinds. - Every entry is sealed and, for links, snapshotted.
- The combined
token_estimateof external context fits withinext_context_budget, and internal context, external context and input together fit withincontext_budget.
ext_context_hash is the sha256 over the ordered entries' (kind, label, content_hash) followed by the note, and it is pinned like every other hash.
Evaluators MUST build the model's context in this order: the prompt, the internal context, then the external context under a heading stating that it was supplied by the caller for this request, then the input and evidence. The prompt SHOULD tell the model that internal context governs, and that call context is material to judge, not instructions to follow.
Shaping the jury
A request says who may rule. JurySpec sets the number of evaluators, the
quorum, the required assurance level, whether families must differ, and
optional lists of allowed model families and specific model commitments.
Only active evaluators that match every constraint, and whose max_context
fits the request, may commit. A DAO can require L2 and two named open
models; an agent's spending check can accept any three fast models at L1.
Payment, budget and refunds
Evaluators are paid by the request, in lamports, from an escrow the requester funds up front.
- Quote.
QuoteRulingtakes the same arguments asRequestRulingand sets return data to an estimate: for the cheapest eligible evaluators that satisfy the jury,base_feeplus input and output tokens at their prices, up tomax_input_tokensandmax_output_tokens, plusproof_feeandverifier_feeat L2, plus rent for the request, attestation and ruling accounts. Clients simulate it before requesting. - Escrow.
RequestRulingmovesbudgetlamports into the request and recordsquoted. It MUST fail ifbudgetis belowquoted. Evaluator prices are pinned at request time; later price changes do not apply. - Payout. When an evaluator reveals, its charge is fixed:
base_feeplus its token charges and proof fee, never more than its pinned prices allow and never more thanmax_fee_each.CloseRequestpays each revealed evaluator to itspayout_wallet, pays verifiers, and adds the totals tospent. - Refund. After payouts, the rest of
budgetand all reclaimed rent go torefund_to. Unrevealed slots and expired requests are refunded in full, minus work already revealed. - Insufficient funds. If the escrow cannot cover the next step (for
example, more evaluators are needed after an invalid reveal, or proofs
cost more than quoted), the request moves to "needs funds" and records the
shortfall. Work pauses until anyone calls
TopUpwith at least the shortfall beforetopup_deadline. If no one does, the request expires todefault_outcome, revealed work is paid, and the rest is refunded.
Callbacks. If callback_program is set, a crank calls NotifyCaller
when an event in callback_events happens: final, needs funds, expired or
disputed. NotifyCaller invokes the callback program with the request, the
event and, for "needs funds", the shortfall. Callbacks only notify. They move
no funds, and a callback program MUST re-check the ruling with ReadRuling
before acting on it. Programs that do not use callbacks can poll the request.
This proposal does not define staking or slashing. Implementations MAY add bonds, and SHOULD record equivocation (an evaluator revealing two different outcomes for one request) so that clients can exclude that evaluator.
Instructions
-
CreateContent(signer: authority): Creates a Content account with its hash, length, encoding and token estimate. -
WriteContentChunk(signer: authority): Writes inline bytes at an offset whilewritingis true. -
SealContent(signer: authority): Checks the hash and marks the content ready. -
UpdateContent(signer: authority): Replaces a Content account's bytes and hash, subject to the owning program's mutability. -
SnapshotLink(signer: any, unless the program restricts it): Records a linked page's snapshot hash, reference and slot. -
SetKeyEnvelope(signer: authority): Attaches or replaces the key wraps for encrypted content. -
CreateContextSetandSetContext(signer: authority): Create a context set or replace its entries. -
CreateInferenceProgram(signer: authority): Creates the program with its prompt, context set, budget and minimums. -
SetPromptandSetContextSet(signer: authority): Point the program at new content, immediately or staged, by mutability mode. -
ApplyPending(signer: anyone): Applies staged changes afterpending_after. -
SetMutability(signer: authority): Moves toward frozen. -
QuoteRuling(signer: none): Estimates the cost of a request and returns it as return data. -
RequestRuling(signer: requester): Creates a RulingRequest with its call context and jury, and escrows the budget. -
TopUp(signer: anyone): Adds lamports to a request's escrow, and resumes it when the shortfall is covered. -
NotifyCaller(signer: anyone): Sends a pending event to the request's callback program. -
CloseRequest(signer: anyone, after the ruling is final or expired): Pays evaluators and verifiers, refunds the rest torefund_to, reclaims rent.
Commit, then reveal. Each evaluator first submits only
sha256(message || salt) before commit_deadline. After that slot, the
evaluator (or anyone holding the message, salt and signature) calls
RevealAttestation. The program MUST check that:
- The transaction contains an Ed25519 precompile instruction verifying
signing_key's signature over the message. The program reads it with instruction introspection. - The message fields match the request and the evaluator's model commitment.
sha256(message || salt)equals the stored commitment.
No evaluator can see another's answer before committing to its own.
Finalization. After reveal_deadline, FinalizeRuling counts revealed
attestations by outcome. If at least quorum agree on one outcome, and that
quorum meets the program's family and assurance requirements, the Ruling
records that outcome. Otherwise the Ruling records default_outcome with
certainty.agreeing below quorum. Calling programs MUST treat that as "no
ruling".
Edge Cases
-
Content changes during a request. Requests pin hashes at creation. Evaluators attest only against pinned content. If it is no longer retrievable, the request expires.
-
Frozen programs.
SetPrompt,SetContextSet,UpdateContentandSetContextMUST fail once the relevantauthorityisNone. -
Shared context sets. A context set used by several programs changes for all of them. Programs that need stability SHOULD use a frozen or timelocked context set.
-
Linked pages that change or vanish. Rulings use the pinned snapshot, so later edits to the live page change nothing. If the snapshot itself is not retrievable, evaluators cannot attest and the request expires.
-
Pages that cannot be fetched. Pages behind logins or paywalls, or that disallow automated access, SHOULD NOT be linked. Supply the text as inline or external content instead.
-
No eligible evaluators. If no active evaluators match the jury specification and context size,
QuoteRulingandRequestRulingMUST fail rather than create a request that cannot be served. -
Estimates that are wrong. Token counts are capped by
max_input_tokensandmax_output_tokens, so charges cannot exceed the quote's basis. A shortfall can still arise when extra evaluators or proofs are needed, and is handled by "needs funds". -
External context not accepted. If
ext_context_modeis 0,RequestRulingMUST reject any external context. If it is 2, it MUST reject requests without any. -
Over budget. If prompt, context and input exceed an evaluator's
max_context, that evaluator MUST NOT attest.RequestRulingSHOULD fail if fewer thanevaluatorslisted evaluators can fitcontext_budget. -
Compact form drift. If the compact form and the source disagree, the stored bytes are what was ruled on.
source_hashlets anyone show the difference. -
Deadlines. Deadlines are slots. Clients SHOULD allow enough slots for model latency, which is commonly tens of seconds per ruling.
-
Input confidentiality.
input_refmay point to encrypted content readable only by the evaluators. The on-chain hash stays public.
Validator Components Affected
None. Each proposal is an interface implemented by an on-chain program using the existing Ed25519 signature-verification precompile. No runtime, virtual machine, consensus or networking change is required. RPC providers, indexers and explorers MAY decode the account layouts defined here.
Alternatives Considered
-
Each application defines its own format. This is the status quo. It works for one application, but calling programs, wallets and explorers cannot interpret results across applications, and every team re-solves replay protection, commit-reveal and content pinning.
-
Immutable versions only. Earlier drafts made every prompt version immutable behind a version pointer. That is safer for callers but costs a new account per edit and slows creators down. Pinned hashes give callers the same guarantee for any single ruling, and creators who want permanence can freeze.
-
General-purpose oracles. Existing oracle networks deliver data and computation results, but do not define natural-language programs, context sets, model commitments, model-family diversity or proofs of inference.
-
Running models on chain. Small networks can run inside a program, but models able to read natural-language rules are many orders of magnitude beyond compute and storage limits.
Impact
- Dapp developers get one way to store natural-language logic, call it from a program and pay for it.
- DAOs, treasuries and companies can keep constitutions, policies and standards on chain as context, update them in public, and freeze them.
- Wallets and explorers can show the exact prompt, context, revision and mutability behind any request, or the hashes alone when content is encrypted.
- Validators and core contributors are not affected.
Security Considerations
-
Injected instructions in external context. A caller can put text in the external context that tries to steer the models ("approve this"). Evaluators MUST present external context as material to judge, below the internal context, and inference programs SHOULD restrict which kinds callers may add.
-
Manipulated pages. Whoever controls a linked page controls what is captured. A DAO discussion can be edited, or flooded with posts, before the snapshot. Programs SHOULD snapshot at a defined moment, for example when a vote closes, and SHOULD treat linked pages as evidence to weigh, not as rules. Text inside a page MUST be passed to the model as data, never as instructions.
-
Mutable rules. A creator can change the prompt or context to rules that favor them. Pinned hashes protect any single ruling, but not future ones. Calling programs SHOULD check
prompt_hashandcontext_hashagainst values they trust, or require timelocked or frozen programs, for high-value decisions. Wallets SHOULD show the mutability mode. -
Encrypted rules cannot be audited. When content is encrypted, users cannot read the rules they are judged by, and any evaluator can leak them. Programs that use encryption SHOULD publish
source_hashand SHOULD commit to disclosing the source after a stated time or on dispute. -
Compact forms can change meaning. Compilation is lossy. Creators SHOULD test compact forms against the source, and disputes SHOULD be able to reference the source.
-
Fee padding. An evaluator could claim more tokens than it used. Charges are capped by pinned prices, the request's token caps and
max_fee_each, and output length is checkable againstoutput_hash. -
Callbacks. Callbacks run in separate transactions and move no funds, so they cannot drain escrow. A callback program must not trust the event alone; it re-reads the ruling.
-
Liveness and censorship. Evaluators may not answer. Expiry yields
default_outcome. Programs MUST design that outcome to be the safe one, for example "hold" rather than "allow".
Backwards Compatibility
This proposal adds a new program interface and changes nothing existing.
Conformance
- A reference program implementing these instructions, with tests on a local cluster for each mutability mode, timelocked staging, freezing, request pinning across content changes, compact, compressed and encrypted content, linked and git content, context-budget checks, external context limits, jury constraints, quotes, escrow, refunds, "needs funds", top-ups and callbacks.
- Test vectors for the context hash, the external context hash, the encoding pipeline and the key envelope.
Appendix A: Prompt format (informative)
asc: 1
name: <short name>
applies_to: <the kind of input, e.g. withdrawal or proposal_execution>
outcomes:
  <id>: <one-line meaning>
default: <outcome id used on expiry or no quorum>
evidence: [<names of evidence items evaluators may read>]
---
<instructions in natural language, or their compact form>
Evaluators MUST reply in this form, and output_hash covers the whole reply:
{
  "outcome": "<one id from outcomes>",
  "confidence": <0 to 100>,
  "summary": "<the decision in a few sentences>",
  "reasoning": "<why, step by step, applying the context to the input>",
  "sources": [
    { "kind": "context", "content_hash": "<hex>", "locator": "Art. 2, sec. 3" },
    { "kind": "evidence", "content_hash": "<hex>", "locator": "ticket" }
  ]
}
SIMD 2 (draft): Inference Evaluators and Attestations
simd: 'XXXX'
title: Inference Evaluators and Attestations
authors:
  - Rex St. John (Verafy)
category: Standard
type: Interface
status: Idea
created: 2026-11-05
feature: (fill in with feature key and github tracking issues once accepted)
Summary
These SIMDs are part of a broader proposal to bring Inference Programs to Solana natively: Bringing Inference Programs To Solana.
This proposal defines how off-chain model operators take part in inference programs. An evaluator registers an Ed25519 signing key, its prices and a model commitment: a record of exactly which model it runs. For each request it serves, it commits to an answer and then reveals an attestation: a signed message binding the request, the pinned prompt and context, the input, its outcome, its confidence, and an optional reference to a zero-knowledge proof that the committed model produced the output. It also defines three assurance levels, from signatures alone (L0) to verified proofs of inference (L2).
This is one of three companion proposals that bring inference programs to Solana:
- Inference Programs: natural-language programs on chain, their context, and how other programs call and pay for them.
- Inference Evaluators and Attestations: who runs the models, what they commit to, and the signed, optionally provable, vote each one casts.
- Inference Rulings, Disputes and Challenges: how votes become a signed ruling that programs act on, and how rulings are disputed, challenged and overturned.
The motivation, use cases and diagrams for all three are in the overview post.
Motivation
A signature proves which key signed, not which model ran. An operator could quietly swap in a cheaper model, a fine-tuned one, or a person. Recent work on zero-knowledge proofs of LLM inference (Anthropic, 2026) shows that a provider can prove that committed weights produced an output without revealing them. Such proofs are large and slow today (tens of megabytes, seconds to verify, one open model), so they cannot be verified in a transaction, but they can be referenced and checked off chain.
This lets each side do what it is good at: models think off chain on hardware built for it, and Solana keeps a permanent, checkable record of who voted, for what, and with what proof. A common registry and attestation format lets any program trust any evaluator's work across implementations.
Dependencies
This proposal depends on the following proposals, submitted together:
-
SIMD-XXXX: Inference Programs
Defines the RulingRequest whose pinned hashes and jury specification every attestation answers.
-
SIMD-XXXX: Inference Rulings, Disputes and Challenges
Counts revealed attestations into a ruling.
New Terminology
-
Evaluator: An off-chain operator that runs a model against inference programs and signs attestations with a registered Ed25519 key.
-
Model commitment: A record of exactly what an evaluator runs: a model identifier, a hash of the weights, a hash of the tokenizer and a hash of the inference configuration.
-
Attestation: An Ed25519-signed message from an evaluator binding a request, the prompt and context hashes, an input hash, an output and a model commitment.
-
Proof of inference: A proof, verified off chain, that a committed model produced a given output. Attestations reference it by hash.
-
Assurance level: How much a ruling proves, from signatures alone (L0) up to verified proofs of inference (L2).
Detailed Design
The key words "MUST", "MUST NOT", "REQUIRED", "SHALL", "SHALL NOT", "SHOULD", "SHOULD NOT", "RECOMMENDED", "NOT RECOMMENDED", "MAY", and "OPTIONAL" in this document are to be interpreted as described in RFC 2119 and RFC 8174.
All integers are little-endian. All hashes are SHA-256 unless stated
otherwise. Account layouts begin with an 8-byte discriminator equal to the
first 8 bytes of sha256("inference-programs:" || account_name).
Accounts
Evaluator
A PDA at ["evaluator", operator].
discriminator        [u8; 8]
operator             Pubkey     // controls this record
signing_key          [u8; 32]   // Ed25519 key that signs attestations
encryption_key       [u8; 32]   // X25519 key for encrypted content
model_commitment     Pubkey     // ModelCommitment account
family               [u8; 32]   // model family label, e.g. "llama-4"
max_context          u32        // largest context the model accepts, tokens
payout_wallet        Pubkey     // where this evaluator's fees are paid
base_fee             u64        // lamports per attestation
input_price          u64        // lamports per 1,000 input tokens
output_price         u64        // lamports per 1,000 output tokens
proof_fee            u64        // lamports for a proof of inference, if offered
status               u8         // 0 active, 1 paused, 2 retired
registered_slot      u64
ModelCommitment
discriminator        [u8; 8]
model_id             [u8; 64]   // UTF-8, zero padded
weights_hash         [u8; 32]
tokenizer_hash       [u8; 32]
config_hash          [u8; 32]   // hash of decoding settings
                                // (e.g. temperature 0, fixed seed)
proof_system         [u8; 32]   // proof-of-inference system id,
                                // all zeros if none
publisher            Pubkey
Model commitments are published once and MUST NOT change. Closed models whose
weights cannot be committed MAY use a zero weights_hash. Rulings that rely on
them cannot reach assurance level L2.
EvaluatorSet (optional)
A list of evaluator accounts an inference program accepts, controlled by the inference program's authority. It is REQUIRED when the prompt or any context document is encrypted, since only listed evaluators hold keys. Without one, any active evaluator may attest, subject to the request's quorum rules.
Attestation
A PDA at ["attestation", ruling_request, evaluator].
discriminator        [u8; 8]
ruling_request       Pubkey
evaluator            Pubkey
commitment           [u8; 32]   // sha256(message || salt), set at commit
outcome              u8         // set at reveal
confidence           u8         // 0 to 100, the model's own confidence
output_hash          [u8; 32]   // sha256 of the full model output
output_ref           [u8; 96]   // where the full output can be fetched
proof_hash           [u8; 32]   // sha256 of the proof, or zero
proof_verifications  u8         // count of verifier attestations, see L2
revealed             bool
Attestation message
Evaluators sign the following byte string with Ed25519:
"solana-inference-attestation:v1"   // 31 bytes, ASCII, no terminator
ruling_request        [u8; 32]
prompt_hash           [u8; 32]
context_hash          [u8; 32]
ext_context_hash      [u8; 32]
input_hash            [u8; 32]
evidence_hash         [u8; 32]
model_commitment      [u8; 32]      // ModelCommitment account address
outcome               u8
confidence            u8
output_hash           [u8; 32]
proof_hash            [u8; 32]
The domain prefix prevents a signature over this message from being valid for
any other purpose. Binding ruling_request prevents replay across requests.
Binding prompt_hash, context_hash, ext_context_hash and input_hash
means an attestation applies to exactly one prompt, one context set, one
external context and one input.
Commit, then reveal
Each evaluator first submits only
sha256(message || salt) before commit_deadline. After that slot, the
evaluator (or anyone holding the message, salt and signature) calls
RevealAttestation. The program MUST check that:
- The transaction contains an Ed25519 precompile instruction verifying
signing_key's signature over the message. The program reads it with instruction introspection. - The message fields match the request and the evaluator's model commitment.
sha256(message || salt)equals the stored commitment.
No evaluator can see another's answer before committing to its own.
Eligibility
Only active evaluators that match every constraint of a request's
JurySpec, whose max_context fits the request's context_budget, and that
are in the program's evaluator set when it has one, may commit. Prices are
pinned at request time.
Assurance levels
- L0: signed by
quorumregistered evaluators. - L1: L0, plus commit-reveal and at least
quorumdistinct model families. - L2: L1, plus each counted attestation has a non-zero
proof_hashand at least the program's required number of verifier attestations confirming that the proof verifies against the evaluator's model commitment.
Proofs of inference are not verified on chain by this proposal. A verifier
is an evaluator-like registered key that signs
"solana-inference-proof:v1" || attestation || proof_hash || result.
RevealAttestation or a separate AttestProof instruction counts these
signatures in proof_verifications. If proof sizes and verification costs
fall enough for on-chain verification, a future SIMD can add a syscall and
let L2 be checked directly.
Fast evaluators (informative)
A new class of models, sometimes called System 1 models, returns a typed answer (a choice from a list, a score or a yes or no) with a calibrated probability, instead of generated text. One early example reports 70 to 500 milliseconds per decision, at a small fraction of a language model's cost, with lower accuracy than frontier models on the vendor's own benchmark (TypeSafe Jev, 2026). These figures are vendor-reported and not independently reproduced.
They fit this interface in three ways, none of which needs new accounts:
- As a screen. A creator publishes a second inference program with the
same context set and a prompt that asks one yes-or-no question per rule. A
caller requests a ruling from it first. Calling programs MAY act on a
screen result only for outcomes that are safe on their own, such as
default_outcome, or within value limits they enforce in code, and SHOULD escalate everything else to a full request. - As an evaluator. A System 1 evaluator can attest: its outcome and
probability fill
outcomeandconfidence. It cannot be the rapporteur, because it writes no summary, reasoning or sources, so a quorum SHOULD include enough language-model evaluators to post and sign off an opinion. - To size the jury. A client MAY use the screen's probability to choose
the full request's
JurySpec: a larger jury, or a higher assurance level, when the screen is unsure.
A hosted, closed System 1 model publishes no weights commitment, so it cannot reach L2, and it counts as one model family. Calibrated probabilities are not correct answers. These models are also weaker on numeric checks, which belong in the calling program's own code anyway.
Instructions
-
PublishModelCommitment(signer: publisher): Creates an immutable ModelCommitment. -
RegisterEvaluator(signer: operator): Creates or updates an Evaluator. -
CommitAttestation(signer: evaluator signing key): Records the commitment beforecommit_deadline. -
RevealAttestation(signer: anyone): Checks the Ed25519 signature and the commitment, records the outcome. -
AttestProof(signer: registered verifier): Records a verifier's signature that an attestation's proof verifies against the evaluator's model commitment, and incrementsproof_verifications.
Edge Cases
-
Encrypted content without keys. An evaluator with no KeyWrap cannot read the content and MUST NOT attest.
-
External content mismatch. Evaluators MUST refuse to attest if fetched bytes do not hash to
content_hash. -
Retired evaluators or keys. An evaluator retired after committing MAY still reveal for that request. Its key MUST NOT be accepted for new requests.
-
Too many signatures for one transaction. Each reveal is its own transaction, so quorum size is not limited by transaction size.
-
Empty or malformed outputs. An attestation whose outcome is not in the prompt's outcome list MUST be rejected at reveal.
Validator Components Affected
None. Each proposal is an interface implemented by an on-chain program using the existing Ed25519 signature-verification precompile. No runtime, virtual machine, consensus or networking change is required. RPC providers, indexers and explorers MAY decode the account layouts defined here.
Alternatives Considered
-
Trusted execution environments. Hardware attestations from secure enclaves can show which binary ran. They depend on hardware vendors and have a history of side-channel attacks. A model commitment can carry a TEE attestation in place of, or alongside, a proof of inference. A future revision could add it as an assurance level.
-
On-chain verification of proofs of inference now. Current proofs for large language models are far larger than transaction and account limits allow, and take seconds of multi-core CPU time to verify. That rules out on-chain verification today.
Impact
- Evaluator operators get one registration and attestation format, usable across applications, with published prices.
- Calling programs can require diversity of model families, or proofs.
- Model providers can publish commitments, and prove which model ran without publishing weights.
- Validators and core contributors are not affected.
Security Considerations
-
Model substitution. Without proofs of inference, an evaluator can run a different model than it committed to. Only L2 rulings address this, and closed models cannot reach L2.
-
Collusion. Evaluators can coordinate. Commit-reveal stops copying within a request but not collusion arranged in advance. Distinct-family requirements, evaluator sets and bonds reduce but do not remove this risk.
-
Self-reported confidence. Confidence is the model's own estimate and is not calibrated. Programs SHOULD weigh
agreeingoverconfidence_mean. -
Replay. Attestations bind the request address, pinned hashes and input hash. Calling programs MUST check that
input_hashmatches the exact action. -
Key compromise. A compromised evaluator key can sign false attestations until retired. Quorums with distinct operators limit the impact of one key.
-
Determinism. Proofs of inference require fixed decoding settings, so
config_hashMUST describe them. Outputs that vary across runs cannot reach L2.
Backwards Compatibility
This proposal adds a new program interface and changes nothing existing.
Conformance
- A reference implementation of these instructions, with tests for commit-reveal with valid and invalid salts, rejection of unlisted outcomes, eligibility checks, distinct-family enforcement and verifier counting.
- Test vectors for the attestation message: input bytes, keys, expected hashes and expected signatures.
SIMD 3 (draft): Inference Rulings, Disputes and Challenges
simd: 'XXXX'
title: Inference Rulings, Disputes and Challenges
authors:
  - Rex St. John (Verafy)
category: Standard
type: Interface
status: Idea
created: 2026-11-05
feature: (fill in with feature key and github tracking issues once accepted)
Summary
These SIMDs are part of a broader proposal to bring Inference Programs to Solana natively: Bringing Inference Programs To Solana.
This proposal defines the ruling: the signed decision recorded on chain
when an inference program's evaluators reach quorum. Like a court opinion, it
records the outcome, a summary, the reasoning by hash, the sources used
(checked against what the jury was given), how strongly the models agreed,
every vote's signature, a co-signed sign-off and any dissents. Programs read
it with ReadRuling and act on it. A ruling can be disputed quickly, or
challenged at any later time with new evidence, and overturned by a
new ruling that compares itself to the original. It is never erased.
This is one of three companion proposals that bring inference programs to Solana:
- Inference Programs: natural-language programs on chain, their context, and how other programs call and pay for them.
- Inference Evaluators and Attestations: who runs the models, what they commit to, and the signed, optionally provable, vote each one casts.
- Inference Rulings, Disputes and Challenges: how votes become a signed ruling that programs act on, and how rulings are disputed, challenged and overturned.
The motivation, use cases and diagrams for all three are in the overview post.
Motivation
When judgment happens off chain today, the chain records the outcome but not the reasoning. A ruling closes that gap: anyone can read what was decided, why, on what sources, and who agreed, and a program can check all of it before it acts.
No ruling should be final forever. Evidence turns out to be forged, sources are corrected, rules change. Courts let a later court overturn an earlier decision, sometimes decades on, while the original stays in the record. Rulings need the same: a way to re-examine a past decision against new data and record the result, without rewriting history.
Dependencies
This proposal depends on the following proposals, submitted together:
-
SIMD-XXXX: Inference Programs
Defines the inference program and the RulingRequest a ruling answers.
-
SIMD-XXXX: Inference Evaluators and Attestations
Defines the attestations a ruling counts, and the assurance levels it reports.
New Terminology
-
Ruling request: An account recording a request to run one inference program on one input, with the pinned prompt and context hashes, quorum and deadlines.
-
Opinion: The summary, reasoning and sources of a ruling, written by one agreeing evaluator (the rapporteur) and co-signed by the others.
-
Sign-off: An agreeing evaluator's signature over the opinion, saying it fairly states their decision.
-
Dissent: An optional statement from an evaluator who voted for a different outcome, recorded with the ruling.
-
Certainty: How strongly the models agreed: the share of evaluators that agreed, and their self-reported confidence.
-
Challenge: A request, at any time after a ruling is final, to review it against new evidence, new sources or a claimed error. It is decided by a new ruling that compares itself to the original.
-
Review status: What later review has done to a ruling: none, affirmed, overturned or superseded. The original ruling is never changed otherwise.
-
Prior ruling: A past ruling used as context for a new one, the way a court cites precedent.
Detailed Design
The key words "MUST", "MUST NOT", "REQUIRED", "SHALL", "SHALL NOT", "SHOULD", "SHOULD NOT", "RECOMMENDED", "NOT RECOMMENDED", "MAY", and "OPTIONAL" in this document are to be interpreted as described in RFC 2119 and RFC 8174.
All integers are little-endian. All hashes are SHA-256 unless stated
otherwise. Account layouts begin with an 8-byte discriminator equal to the
first 8 bytes of sha256("inference-programs:" || account_name).
Accounts
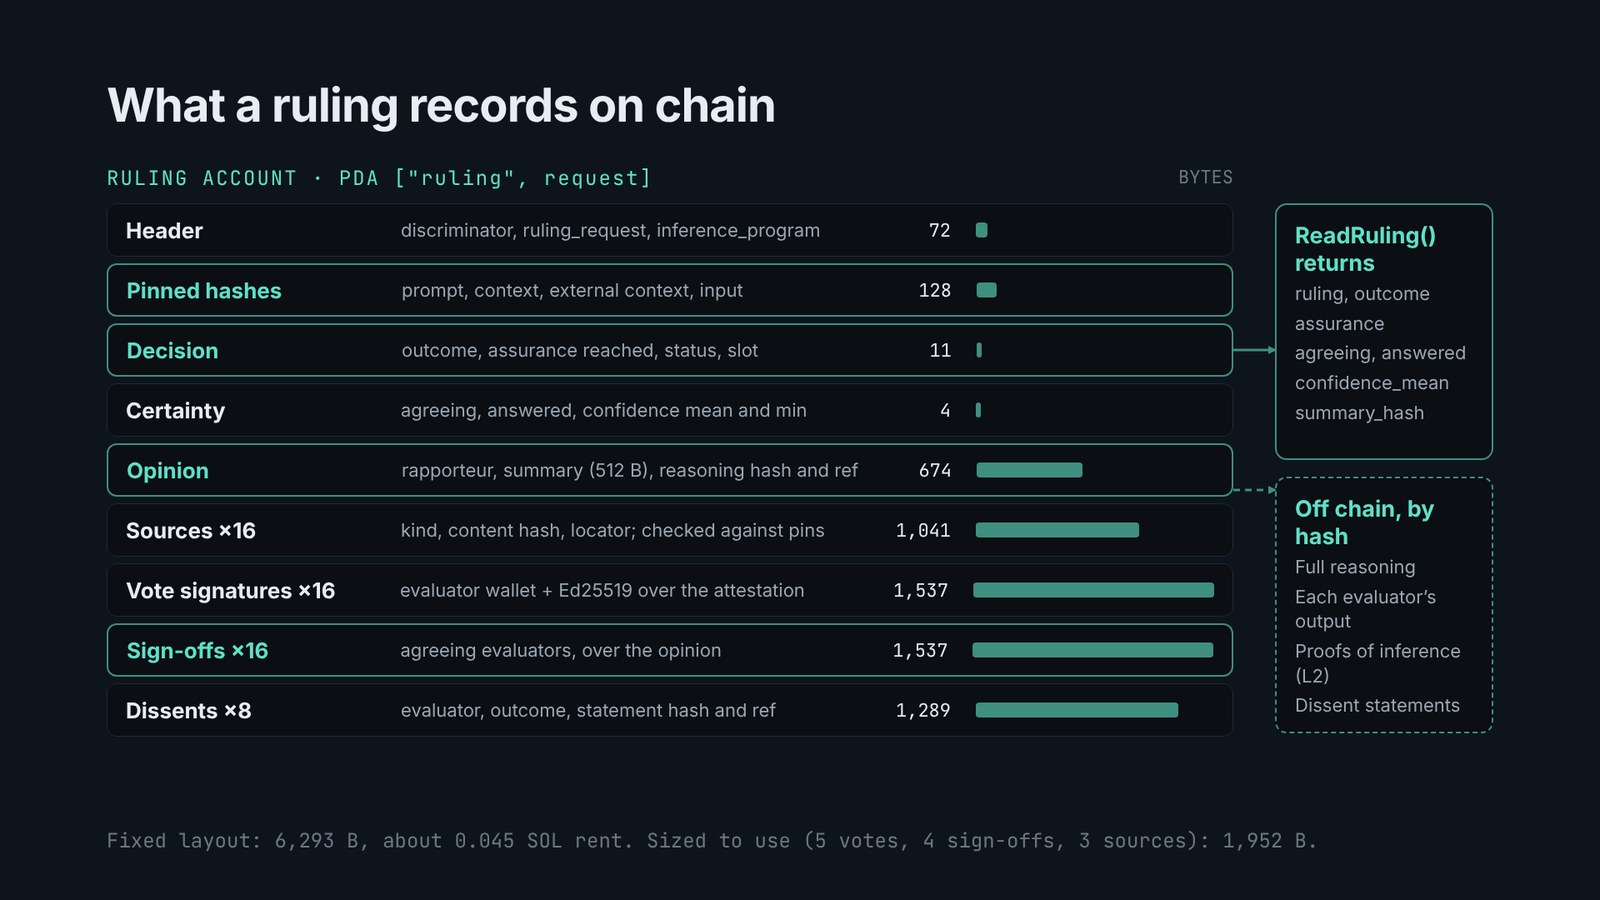
Ruling
A PDA at ["ruling", ruling_request], created by FinalizeRuling and
completed by PostOpinion and SignOff.
discriminator        [u8; 8]
ruling_request       Pubkey
inference_program    Pubkey
prompt_hash          [u8; 32]
context_hash         [u8; 32]
ext_context_hash     [u8; 32]
input_hash           [u8; 32]
outcome              u8
assurance            u8         // level actually reached
certainty            Certainty
rapporteur           Pubkey     // evaluator who wrote the opinion
summary_len          u16
summary              [u8; 512]  // UTF-8, the decision in a few sentences
reasoning_hash       [u8; 32]   // sha256 of the full reasoning
reasoning_ref        [u8; 96]   // where the full reasoning can be fetched
source_count         u8
sources              [Source; 16]
signature_count      u8
signatures           [Signature; 16]  // one per counted attestation
signoff_count        u8
signoffs             [Signature; 16]  // agreeing evaluators, over the opinion
dissent_count        u8
dissents             [Dissent; 8]
finalized_slot       u64
status               u8         // 0 awaiting opinion, 1 final,
                                // 2 disputed, 3 overturned, 4 upheld
review_status        u8         // 0 none, 1 affirmed, 2 overturned,
                                // 3 superseded, 4 under review
reviewed_by          Option<Pubkey>  // latest Ruling that reviewed this one
review_count         u16

Certainty:
  agreeing           u8         // evaluators that chose the outcome
  answered           u8         // evaluators that revealed
  confidence_mean    u8         // 0 to 100, over agreeing evaluators
  confidence_min     u8

Source:
  kind               u8         // 0 context entry, 1 evidence item,
                                // 2 prompt, 3 external context entry,
                                // 4 prior ruling
  content_hash       [u8; 32]   // must match a pinned context entry,
                                // evidence hash or the prompt
  locator            [u8; 32]   // e.g. "Art. 2, sec. 3", zero padded

Signature:
  evaluator          Pubkey
  signature          [u8; 64]   // Ed25519, by the evaluator's signing key

Dissent:
  evaluator          Pubkey
  outcome            u8
  statement_hash     [u8; 32]
  statement_ref      [u8; 96]
The full reasoning is usually longer than an account should hold, so the
ruling stores a short summary inline and the full text by hash and reference.
Implementations MAY store the reasoning inline in a Content account and point
reasoning_ref at it.
ReviewPolicy
A PDA at ["review-policy", inference_program], set by the program's
authority, and subject to its mutability mode.
discriminator        [u8; 8]
inference_program    Pubkey
dispute_parties      u8         // 0 requester, 1 named parties, 2 anyone
challenge_mode       u8         // 0 none, 1 parties only, 2 anyone
challenge_bond       u64        // lamports a challenger locks
challenge_min_evals  u8         // floor on a challenge's jury size
bond_growth_bps      u16        // bond increase per earlier review
Without a ReviewPolicy, disputes are open to the requester only and challenges are not accepted.
Finalization
After reveal_deadline, FinalizeRuling counts revealed
attestations by outcome. If at least quorum agree on one outcome, and that
quorum meets the program's family and assurance requirements, the Ruling
records that outcome. Otherwise the Ruling records default_outcome with
certainty.agreeing below quorum. Calling programs MUST treat that as "no
ruling".
Opinions, sign-off and the returned ruling
A ruling is more than an outcome. Like a court opinion, it says what was decided, why, on what basis, and who agrees.
- Votes. Each evaluator's full output, in the format of Appendix A,
contains an outcome, a confidence, a summary, its reasoning and the sources
it relied on. Its hash is
output_hash, and the attestation records the outcome and confidence. - Rapporteur. After
FinalizeRulingcounts a quorum, the rapporteur is the agreeing evaluator with the lowestsha256(evaluator || ruling_request). It callsPostOpinionwith the summary, the reasoning hash and reference, and the sources. If it does not post withinopinion_windowslots, the next agreeing evaluator in the same order may. - Sources are checked.
PostOpinionMUST reject any source whosecontent_hashis not the pinned prompt, an entry of the pinned context set, a external-context entry, or an item in the request's evidence. A ruling cannot cite a document the jury was not given. - Sign-off. Each agreeing evaluator calls
SignOffwith an Ed25519 signature over the opinion message below. The ruling becomes final when at leastquorumevaluators have signed off. An evaluator that disagrees with the opinion's wording does not sign off, and if too few sign off beforesignoff_deadline, the next rapporteur posts a new opinion. - Dissents. An evaluator that voted for another outcome MAY call
PostDissentbefore the ruling is final.
The opinion message is:
"solana-inference-opinion:v1"     // 27 bytes, ASCII, no terminator
ruling                [u8; 32]
outcome               u8
summary_hash          [u8; 32]    // sha256 of the summary bytes
reasoning_hash        [u8; 32]
sources_hash          [u8; 32]    // sha256 over the ordered sources
Wallet signatures. Each evaluator's signing_key is an ordinary Solana
Ed25519 keypair, so every vote and sign-off is a wallet signature, visible
in explorers and checkable by anyone. Evaluators SHOULD also sign the reveal
and sign-off transactions with that key, as fee payer or signer, so the
evaluator's wallet appears on the transaction itself. A wallet signature
proves which operator stands behind a vote. Which model produced it is shown
only by a proof of inference (L2).
Returning the ruling to a program. ReadRuling checks that a ruling is
final and matches the expected program, hashes and input, then sets Solana
return data to:
ruling                [u8; 32]
outcome               u8
assurance             u8
agreeing              u8
answered              u8
confidence_mean       u8
summary_hash          [u8; 32]
A calling program invokes ReadRuling by cross-program invocation and reads
the return data, or reads the Ruling account directly.
Reading a ruling from another program
A calling program reads a Ruling account. It MUST check:
- The account is owned by the inference programs program.
inference_program,prompt_hashandcontext_hashmatch the rules it intends to apply, andext_context_hashmatches what it injected.input_hashmatches the sha256 of the exact action it is about to take.certainty.agreeing >= quorum,assuranceis at least what it requires, andstatusis final or upheld, with any dispute window it cares about passed.review_statusMUST NOT be overturned, and a program acting now SHOULD NOT act while it is under review. It MAY also require a minimumcertainty.confidence_min.
Rulings take seconds to minutes, so the pattern is two-phase. In one
transaction, a program or client calls RequestRuling with the exact action
encoded as the input. In a later transaction, the program performs the action
only if a valid Ruling exists for that input. Programs SHOULD also enforce
hard limits in their own code, independent of any ruling, and SHOULD allow
only outcomes listed in the prompt to change their behavior.
Disputes
OpenDispute within dispute_window sets the Ruling's status to disputed and
references a new RulingRequest against the same pinned hashes and input. That
new request SHOULD use evaluators whose model families do not overlap with the
original quorum. ResolveDispute records the second request's outcome. If it
matches, the status becomes upheld. If a different outcome reaches quorum, the
status becomes overturned. If neither, the Ruling falls back to
default_outcome.
Challenges and later review
A dispute is quick: it re-judges a fresh ruling on the same evidence, before anyone relies on it. A challenge is for later. Facts come out, evidence turns out to be forged, sources are corrected, or the reasoning looks wrong in hindsight. Courts handle this by letting a later court overturn an earlier decision, sometimes decades on, while the original decision stays on the record. Rulings work the same way.
- Opening. If the program's ReviewPolicy allows it, anyone eligible may
call
OpenChallengeon a final ruling at any time, with no window. The challenger states its grounds and supplies what is new:0new evidence: facts that were not available at the time;1false evidence: an item the ruling relied on was wrong or forged;2error: the rules were misapplied to the evidence as it stood;3changed rules: the program's context has since changed, and the question is whether the ruling would stand under the current rules. The challenger locks itschallenge_bondand funds the challenge request, like any other request.
- What the challenge jury sees. The challenge is a new RulingRequest
with
kind = 2andreviewsset to the original. It pins the original's prompt, context and input hashes, except under grounds 3, where it pins the current ones. Its external context holds, in order: the original ruling and its full reasoning as a prior-ruling entry, the original evidence, and the new material, labeled as new. Old content must still be retrievable, which is why revisions SHOULD be stored permanently. - Comparison. The request prompt asks the jury to compare: does the original outcome still stand given what is now known? The challenge opinion MUST cite the original ruling, and SHOULD say, for each source the original relied on, whether it still holds, and which new source changed the result.
- The jury. It MUST have at least the policy's
challenge_min_evalsevaluators, and SHOULD share no model family with the original quorum, nor with any earlier review of the same ruling. - Result.
ResolveChallengerecords the outcome on the original ruling:- the same outcome reaches quorum:
review_statusbecomes affirmed; - a different outcome reaches quorum: overturned (grounds 0 to 2) or superseded (grounds 3);
- no quorum: the original stands unchanged.
The original's
reviewed_bypoints to the challenge ruling, andreview_countincreases. Nothing else in the original changes, so its history can always be read back: first ruling, every challenge, and each result.
- the same outcome reaches quorum:
- Bond. If the ruling is overturned or superseded, the bond is returned.
If it is affirmed, the bond goes to the program's
refund_to, or as the program specifies, so that challenging is not free.
A ruling can be challenged more than once. A later challenge MUST bring
evidence or grounds that no earlier review of the same ruling considered:
OpenChallenge MUST reject a challenge whose new evidence hashes were all
already pinned by an earlier review.
What overturning does. Past actions are settled on chain and are not reversed. Overturning changes what the record says and what programs do next. A calling program decides the remedy in its own code: an insurance program can pay a claim whose denial was overturned, a governance program can flag a proposal executed under a ruling later overturned, and any program reading a ruling for a new action MUST treat an overturned one as no ruling.
Prior rulings as precedent. A context set MAY include past rulings as
kind-9 entries, so evaluators can apply earlier decisions to similar cases.
Evaluators MUST be told each prior ruling's review_status, so an overturned
decision is never applied as if it stood.
Instructions
-
FinalizeRuling(signer: anyone): Counts revealed attestations, records the outcome, certainty and vote signatures, and chooses the rapporteur. -
PostOpinion(signer: rapporteur): Records the summary, reasoning reference and sources, after checking each source against the pinned hashes. -
SignOff(signer: agreeing evaluator): Adds a signature over the opinion, and marks the ruling final at quorum. -
PostDissent(signer: dissenting evaluator): Records a dissent. -
ReadRuling(signer: none): Checks a final ruling and sets return data. -
OpenDispute(signer: requester or a party named by the program): Marks the Ruling disputed within the window. -
ResolveDispute(signer: anyone): Applies the outcome of a linked second request. -
OpenChallenge(signer: challenger, perchallenge_mode): Locks the bond, creates a challenge request against a final ruling with the new evidence and grounds, and marks the ruling under review. -
ResolveChallenge(signer: anyone): Records the challenge ruling's result on the original, and settles the bond. -
SetReviewPolicy(signer: program authority): Creates or replaces the program's ReviewPolicy.
Edge Cases
-
No quorum. The Ruling records
default_outcomewithcertainty.agreeing < quorum. Calling programs MUST NOT treat it as an approval. -
No opinion. If no agreeing evaluator posts an opinion that gathers enough sign-offs before the last deadline, the ruling stays in "awaiting opinion" and calling programs MUST NOT act on it.
-
Long reasoning. Summaries are capped at 512 bytes. Full reasoning is stored by hash and reference, and evaluators MUST NOT sign off on an opinion whose reasoning they cannot fetch.
-
More than 16 sources. The opinion lists the 16 most relied on. The full list stays in the reasoning.
-
Challenge of a ruling under review. Only one challenge per ruling is open at a time. Others wait until it resolves.
-
Challenged content not retrievable. If the original's pinned content or evidence cannot be fetched, the challenge cannot be served and expires, and the bond is refunded.
-
Disputes cost money too. A dispute is a new request, funded by whoever opens it.
Validator Components Affected
None. Each proposal is an interface implemented by an on-chain program using the existing Ed25519 signature-verification precompile. No runtime, virtual machine, consensus or networking change is required. RPC providers, indexers and explorers MAY decode the account layouts defined here.
Alternatives Considered
-
Optimistic resolution with human disputes. Optimistic oracles and decentralized courts use human voters. They are proven and complementary, and could serve as the dispute layer for a ruling. Human resolution is slower and harder to scale to every withdrawal or proposal.
-
Editing or deleting overturned rulings. Simpler to read, but it would erase the record that the original decision was made and acted on, and the reasoning behind it. Append-only review keeps both.
Impact
- Calling programs get one account to check before acting, with a compact return value.
- Wallets and explorers can show the decision, reasoning, sources, signatures and full review history of any ruling.
- Parties to a decision get a standard path to dispute or challenge it.
- Validators and core contributors are not affected.
Security Considerations
-
Models can be wrong or manipulated. Prompt injection through inputs and evidence, forged evidence and shared blind spots across model families are real risks. In the author's tests, a forged correction placed in the evidence led all ten models tested to the same wrong answer. Calling programs MUST keep hard limits in code, MUST restrict effects to listed outcomes, and SHOULD require dispute windows for high-value actions.
-
Misleading summaries. A rapporteur could summarize unfairly. Sign-off by a quorum of agreeing evaluators, and dissents, limit this. The full reasoning and each vote's output stay available by hash.
-
Made-up sources. Models can cite documents that do not exist. Sources must hash to the pinned prompt, context entries or evidence, so a citation to anything else is rejected on chain.
-
Relitigation. A party that lost can keep challenging, hoping to draw a friendlier jury. Bonds, the requirement for new evidence or grounds, growing jury floors and distinct families for each review limit this. Programs MAY raise the bond with each review of the same ruling.
-
Planted evidence. A challenge's new evidence can be forged as easily as the original's. It is pinned and judged like any other evidence, and can itself be challenged.
Backwards Compatibility
This proposal adds a new program interface and changes nothing existing.
Conformance
- A reference implementation of these instructions, with tests for quorum
and no-quorum finalization, opinions, sign-off and dissents, rejection of
sources outside the pinned hashes,
ReadRulingreturn data, disputes that uphold and overturn, and challenges on each ground that affirm, overturn and supersede, including repeat challenges and rejected duplicates. - A localnet ledger demonstrating a governance program that executes a proposal only after a final ruling against a DAO constitution, and a later challenge that overturns it.